There are two different stories about Gemini 2.5 right now, and most of the confusion comes from mixing them up.
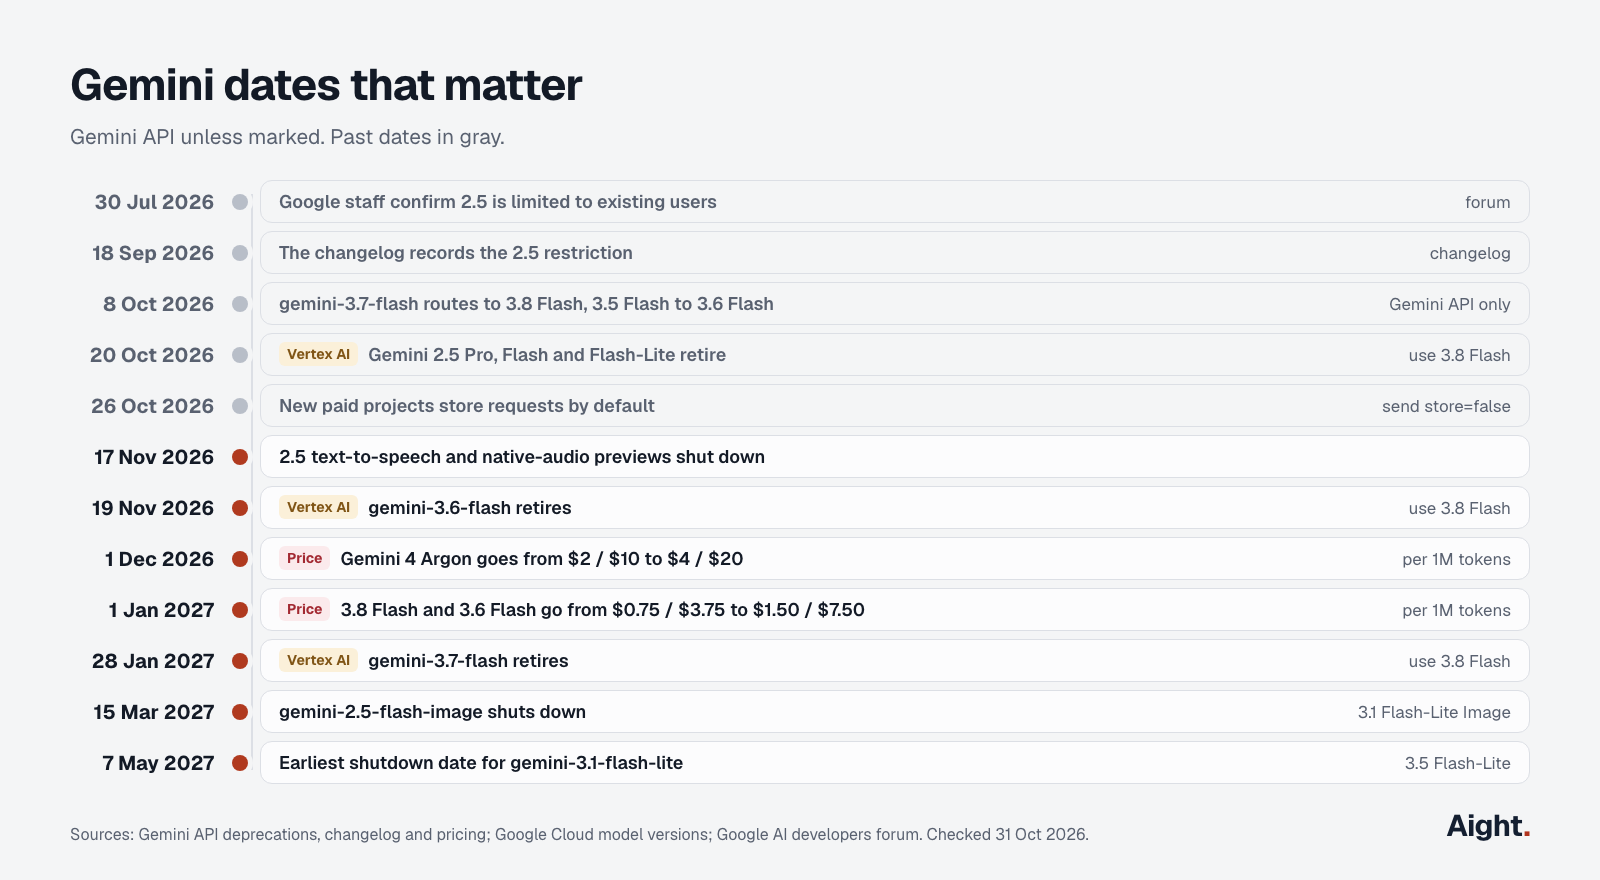
On Vertex AI, which Google now calls Gemini Enterprise Agent Platform, Google set 20 October as the retirement date for Gemini 2.5 Pro, 2.5 Flash and 2.5 Flash-Lite. On the Gemini API, the one you use with an AI Studio key, the same models are not deprecated and have no shutdown date. But Google only serves them to people who were already using them. A new key or a new project gets a 404.
So if your brand-new key gets a 404 while a teammate's old key works fine, nothing is broken. That's the policy.
The error
On the Gemini API it looks like this:
{
  "error": {
    "code": 404,
    "message": "This model models/gemini-2.5-flash is no longer available to new users. Please update your code to use models/gemini-3.8-flash for the latest features and improvements. We recommend you to use the Interactions API (https://ai.google.dev/gemini-api/docs/get-started).",
    "status": "NOT_FOUND"
  }
}
The model the message suggests has changed over time. Reports from September point to gemini-3.6-flash, October ones to gemini-3.8-flash. Go by Google's current recommendation, not the text of an old error.
The restriction is older than most people think. Google staff explained it on the developer forum on 30 July, saying Google is limiting the 2.5 models "to users who have actively used them in the past" to keep performance reliable. The changelog only recorded it on 18 September. Since late September it covers the AI Studio web app too, so 2.5 models may be missing from the model picker there as well. For new projects Google recommends Gemini 3.5 Flash-Lite or 3.8 Flash.
The error also points at the Interactions API. You don't have to move to it: Google says generateContent remains fully supported. But if you're rewriting the call anyway, Google's eight-minute introduction shows what it looks like:
Who can still use Gemini 2.5
| Where | Status | Google's suggested replacement |
|---|---|---|
| Gemini API, existing users | Still works, no shutdown date announced | 3.5 Flash-Lite or 3.8 Flash for new work |
| Gemini API, new users and new keys | 404, "no longer available to new users" | 3.5 Flash-Lite or 3.8 Flash |
| Vertex AI (Gemini Enterprise Agent Platform) | Retirement date was 20 October 2026 | Pro: 3.8 Flash or 3.5 Flash. Flash: 3.8 Flash or 3.5 Flash-Lite. Flash-Lite: those two, or Gemma 4 |
Two related dates people ask about. gemini-2.5-flash-image keeps running until 15 March 2027, with gemini-3.1-flash-lite-image as the replacement. The 2.5 text-to-speech and native-audio preview models on the Gemini API shut down on 17 November.
Check what your key can actually use
Don't trust the model list on its own. A developer with a new paid project reported on Google's forum that 2.5 models still showed up when listing models, while every real request to them returned the 404. A one-line test request is the only reliable check:
from google import genai
from google.genai import errors

client = genai.Client()

# What the key can see
for m in client.models.list():
    if "generateContent" in (m.supported_actions or []):
        print(m.name)

# What the key can actually call
for model in ["gemini-2.5-flash", "gemini-3.5-flash-lite", "gemini-3.8-flash"]:
    try:
        client.models.generate_content(model=model, contents="Reply with OK.")
        print(model, "works")
    except errors.ClientError as e:
        print(model, e.code, e.message)
What it costs to switch
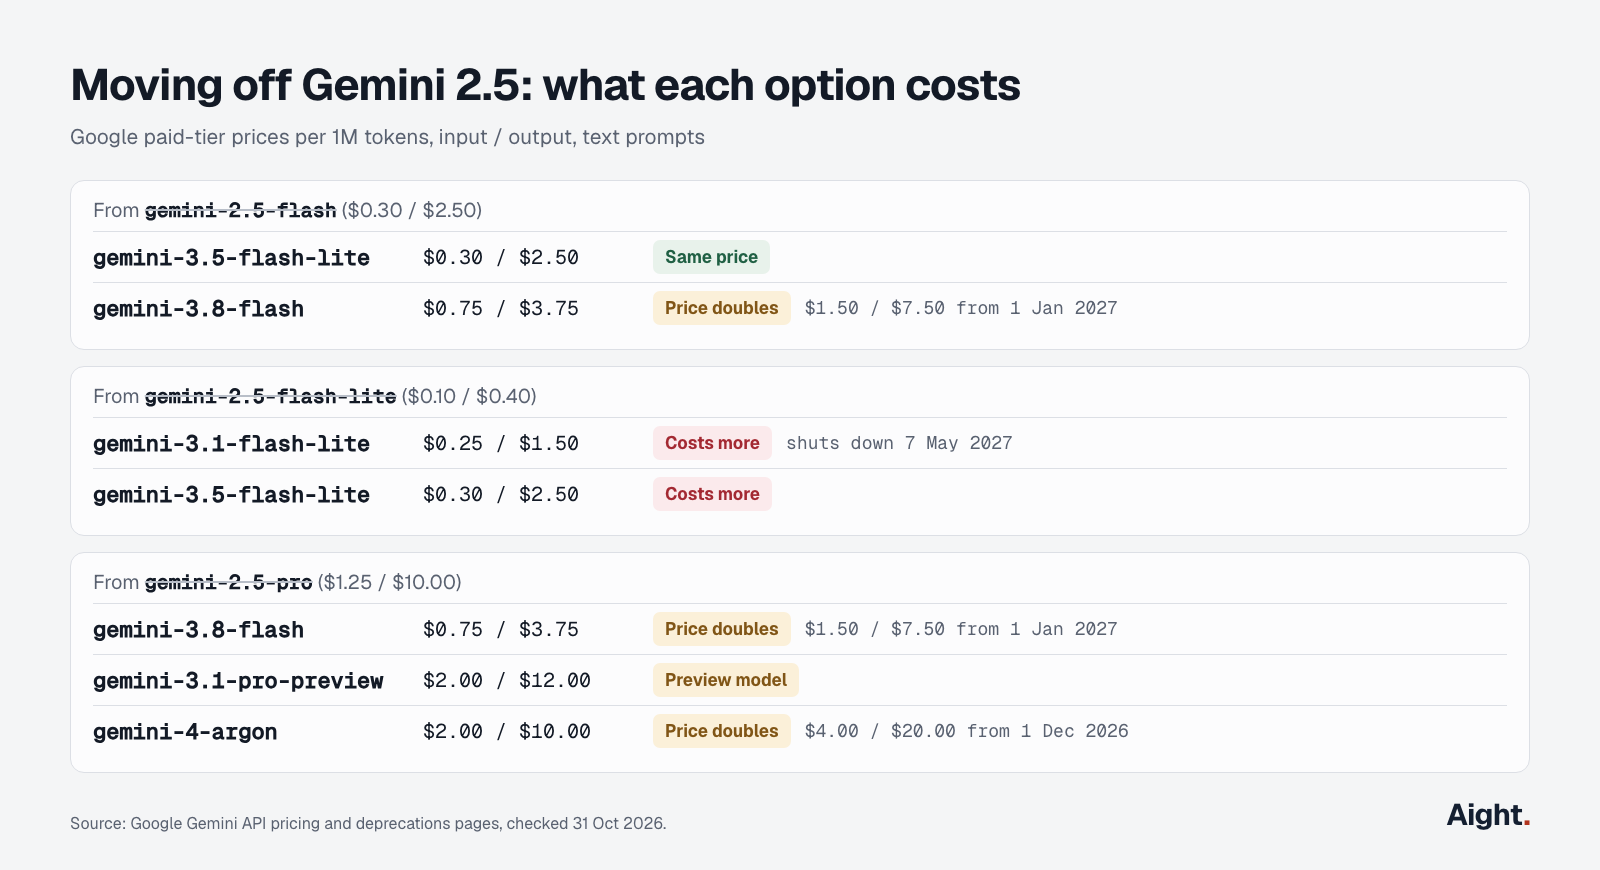
The suggested replacements aren't price-neutral. These are Google's paid-tier prices per million tokens, input / output, for text prompts:
| If you were on | You could move to | Price today | Price later |
|---|---|---|---|
| gemini-2.5-flash ($0.30 / $2.50) | gemini-3.5-flash-lite | $0.30 / $2.50 | No change announced |
| gemini-3.8-flash | $0.75 / $3.75 | $1.50 / $7.50 from 1 Jan 2027 | |
| gemini-2.5-flash-lite ($0.10 / $0.40) | gemini-3.1-flash-lite | $0.25 / $1.50 | Shutdown possible from 7 May 2027 |
| gemini-3.5-flash-lite | $0.30 / $2.50 | No change announced | |
| gemini-2.5-pro ($1.25 / $10.00) | gemini-3.8-flash | $0.75 / $3.75 | $1.50 / $7.50 from 1 Jan 2027 |
| gemini-3.1-pro-preview | $2.00 / $12.00 | Still a preview model | |
| gemini-4-argon | $2.00 / $10.00 | $4.00 / $20.00 from 1 Dec 2026 |
Prompts over 200,000 tokens cost more on the Pro models: gemini-3.1-pro-preview goes to $4 / $18 above that size. Output prices include thinking tokens, which matters more than it used to (see the next section but one).
What stands out:
- If you were on 2.5 Flash, 3.5 Flash-Lite costs exactly the same. Test that one first.
- 2.5 Flash-Lite users have no like-for-like option. The lowest-priced current model, 3.1 Flash-Lite, is 2.5x the input price and close to 4x the output price, and Google lists 7 May 2027 as its earliest possible shutdown date.
- 3.8 Flash looks inexpensive today, but its price doubles on 1 January. Plan your costs on $1.50 / $7.50, not $0.75 / $3.75.
- Google doesn't name a Pro-class replacement for 2.5 Pro. It points to 3.8 Flash. If Flash isn't strong enough for your workload, Gemini 4 Argon is the closest step up, at $2 / $10 until 30 November and $4 / $20 after. It isn't on the free tier, and it only supports automatic (implicit) caching.
If you're weighing Argon, Google's launch conversation covers where it's available and its 1M-token output limit:
One more trap: a few model names now point to other models, and only on the Gemini API. Since 8 October, Gemini API requests to gemini-3.7-flash are routed to gemini-3.8-flash, and gemini-3.5-flash routes to gemini-3.6-flash, which costs more. On Vertex AI those names still mean what they say: gemini-3.5-flash stays available until at least May 2027, gemini-3.6-flash retires on 19 November and gemini-3.7-flash on 28 January 2027. Aliases like gemini-flash-latest also move with every release. Google's own advice is that most production apps should use a specific stable model, so pin the exact name.
The fix
Change the model string. With Google's Python SDK:
from google import genai

client = genai.Client()

response = client.models.generate_content(
    model="gemini-3.5-flash-lite",  # was "gemini-2.5-flash"
    contents="Summarize this support ticket in one line: ...",
)
print(response.text)
What breaks besides the model name
Gemini 3.6 and later changed several request rules. If your 2.5 code sets any of these, the new model will reject it or quietly ignore it:
temperature,top_pandtop_kare ignored on Gemini 4 and Gemini 3.6 and later. For now the API sends back a deprecation warning header. Google says a future release will return a 400, so remove them now.- A request whose last non-empty turn is a model turn (a "prefilled" answer you want the model to continue) now returns a 400.
candidate_countisn't supported on Gemini 3 and later.thinking_budgetis replaced bythinking_level. On 3.8 Flash the levels arelow,medium(the default) andhigh.minimalisn't supported there.- If you use function calling through
generateContent, everyFunctionResponsemust includecall_idandname.
Thinking also changes your bill. 2.5 Flash-Lite didn't think at all by default, and 2.5 Flash could switch it off with thinking_budget=0. The newer models can't fully switch it off:
| Model | Thinking by default | Can you turn it off? |
|---|---|---|
| gemini-2.5-flash-lite | Off | Already off |
| gemini-2.5-flash | Dynamic | Yes, thinking_budget=0 |
| Gemini 3 Flash and Flash-Lite models | On | Not fully |
| gemini-3.8-flash | medium | Not fully. low is the lowest level |
| gemini-4-argon | medium | No |
Thinking tokens are billed as output, and max_output_tokens includes them. Set it too low and the call stops with finish_reason: MAX_TOKENS and an empty or cut-off answer, and you still pay for the thinking. Google suggests lowering thinking_level instead of squeezing the token limit. It also says 3.8 Flash "can use more tokens on longer running and complex tasks, by design", so compare cost per request, not just the per-token price.
from google.genai import types

response = client.models.generate_content(
    model="gemini-3.8-flash",
    contents="Summarize this support ticket in one line: ...",
    config=types.GenerateContentConfig(
        thinking_config=types.ThinkingConfig(thinking_level="low"),  # replaces thinking_budget
        max_output_tokens=2048,  # includes thinking tokens, so leave room
    ),
)
Search grounding is priced differently on Gemini 3
If you use Grounding with Google Search, check this before you switch. On 2.5 models it was 1,500 grounded requests a day free, then $35 per 1,000 grounded prompts. On Gemini 3 and newer it's 5,000 free search requests a month, shared across all those models, then $14 per 1,000 requests, with a cap of 1,500 requests a day. Low-volume apps lose the daily free allowance. High-volume apps pay much less per request.
Free tier and rate limits
3.8 Flash, 3.6 Flash and the Flash-Lite models are available on the free tier. Gemini 4 Argon and 3.1 Pro Preview are paid only. Rate limits apply per project, not per API key, so creating more keys in the same project won't get you more capacity. New paid accounts (Tier 1) also have a spend limit of $10 per 10 minutes and a $250 billing cap, and going over the spend limit returns a 429.
If you're creating a new project for the migration
Since 26 October, new paid-tier projects store Generate Content API requests by default (store=true), and that includes calls made through Google's OpenAI-compatible endpoint. Existing projects keep their setting. Stored logs are kept for 55 days by default, and you can shorten that to 7, 14 or 28 days.
To opt out per request, send store=false. That needs a recent SDK: google-genai 2.33.0 or later for Python, @google/genai 2.31.0 or later for JavaScript. You can also turn off logging for the whole project in the Logs and Datasets settings in AI Studio.
Calling Gemini with the OpenAI SDK
If the rest of your stack uses the OpenAI SDK, Google has an OpenAI-compatible endpoint (still marked beta). Point the client at https://generativelanguage.googleapis.com/v1beta/openai/ and use plain model names like gemini-3.8-flash. reasoning_effort maps to Gemini's thinking levels, but Google notes that reasoning can't be turned off for 2.5 Pro or any Gemini 3 model there either.
Testing Gemini next to other models on Aight
Aight gives you one OpenAI-compatible key for Gemini 3.x and Gemini 4 Argon, alongside Claude, GPT, Grok and DeepSeek. If Google's replacement doesn't do what 2.5 did for you, you can run the same prompts through several candidates and compare them on one bill:
import os
from openai import OpenAI

client = OpenAI(
    base_url="https://api.getaight.ai/v1",
    api_key=os.environ["AIGHT_API_KEY"],
)

prompt = [{"role": "user", "content": "Summarize this support ticket in one line: ..."}]

for model in ["gemini-3.5-flash-lite", "gemini-3.1-pro-preview", "gpt-6-luna", "claude-haiku-4-5"]:
    reply = client.chat.completions.create(model=model, messages=prompt)
    print(model, "->", reply.choices[0].message.content)
Each key can have a monthly spending cap and a list of allowed models, which is handy while you test, so an experiment can't run up a surprise bill. Balance is prepaid in US dollars and doesn't expire. Recharges start at $5 plus a 3% processing fee, with 10% extra balance on each one.
If you switch and still see the 404, look for another place that names gemini-2.5-flash. Framework defaults and SDK wrappers often set their own model, so you can change your code and still hit the old one.
Sources
- Google, Gemini API deprecations and changelog: 18 Sep (2.5 access), 8 Oct (3.7 and 3.5 Flash routing), 13 Oct (Gemini 4 Argon), 26 Oct (storage default)
- Google, Gemini API pricing and rate limits
- Google, What's new in Gemini 3.8, What's new in Gemini 3.6, Thinking and Troubleshooting
- Google, Models and version names, OpenAI compatibility, Logs and datasets
- Google Cloud, Model versions and retirement dates
- Google AI developers forum: staff on the 2.5 restriction, 30 July, AI Studio, 21 September, listing works but requests 404, another 404 report
- openclaw #187357, an example of the 404 in a public project
Checked on 31 October 2026.