For new projects, Gemini API pricing for text models runs from $0.25 / $1.50 per million input / output tokens (Gemini 3.1 Flash-Lite) to $2.00 / $12.00 (Gemini 3.1 Pro Preview). Google's two newest models are on promotional prices: Gemini 4 Argon costs $2 / $10 until 30 November and $4 / $20 from 1 December, and Gemini 3.8 Flash costs $0.75 / $3.75 until 31 December and $1.50 / $7.50 from 1 January 2027. The free tier includes the Flash and Flash-Lite models but not Argon or 3.1 Pro Preview, and Google can use what you send it to improve its products.
Prices below are Google's paid-tier list prices for the Gemini Developer API (the one you call with an AI Studio key), in US dollars, checked on 5 November 2026, followed by three monthly bills set against GPT and Claude.
Gemini API pricing for every current model
Standard tier, per million tokens. Output prices include thinking tokens.
| Model | Input / output | Cached input | Prompts over 200K | Batch and Flex | Free tier |
|---|---|---|---|---|---|
| gemini-4-argon | $2.00 / $10.00, then $4.00 / $20.00 from 1 Dec | $0.10, then $0.20 | No surcharge | $1.00 / $5.00, then $2.00 / $10.00 | No |
| gemini-3.8-flash | $0.75 / $3.75, then $1.50 / $7.50 from 1 Jan 2027 | $0.075, then $0.15 | No surcharge | $0.375 / $1.875, then $0.75 / $3.75 | Yes |
| gemini-3.6-flash | $0.75 / $3.75, then $1.50 / $7.50 from 1 Jan 2027 | $0.075, then $0.15 | No surcharge | $0.375 / $1.875, then $0.75 / $3.75 | Yes |
| gemini-3.5-flash-lite | $0.30 / $2.50 | $0.03 | No surcharge | $0.15 / $1.25 | Yes |
| gemini-3.1-flash-lite | $0.25 / $1.50 | $0.025 | No surcharge | $0.125 / $0.75 | Yes |
| gemini-3.1-pro-preview | $2.00 / $12.00 | $0.20 | $4.00 / $18.00, cached $0.40 | $1.00 / $6.00 | No |
| gemini-3-flash-preview | $0.50 / $3.00 | $0.05 | No surcharge | $0.25 / $1.50 | Yes |
| gemini-2.5-pro | $1.25 / $10.00 | $0.125 | $2.50 / $15.00 | $0.625 / $5.00 | Existing users |
| gemini-2.5-flash | $0.30 / $2.50 | $0.03 | No surcharge | $0.15 / $1.25 | Existing users |
| gemini-2.5-flash-lite | $0.10 / $0.40 | $0.01 | No surcharge | $0.05 / $0.20 | Existing users |
What the table doesn't show:
- Cached input is implicit caching. It's on by default, charges no write fee, and needs a prompt of at least 4,096 tokens on Argon, 3.8 Flash, 3.6 Flash and 3.1 Pro Preview. Explicit caching adds storage by the hour ($0.50 per million tokens per hour on 3.8 Flash until 31 December, $4.50 on 3.1 Pro Preview). Argon supports implicit caching only.
gemini-3.7-flashandgemini-3.5-flasharen't on the price list. Since 8 October, Gemini API requests to them run on 3.8 Flash and 3.6 Flash, at those prices.- The 2.5 models serve only projects that used them before.
Batch costs half and targets a 24-hour turnaround. Flex also costs half but answers synchronously, with best-effort availability (service_tier="flex"). Priority costs 1.8 times Standard (3.8 Flash is $1.35 / $6.75), with rate limits at 0.3 times Standard. Flex and Priority are in preview. An invite-only Contributor tier halves the price in exchange for letting Google use your data.
Grounding with Google Search on Gemini 3 and newer gives paid projects 5,000 free searches a month, then $14 per 1,000, with a cap of 1,500 a day per project. One prompt can trigger several searches, and each is billed.
Other Gemini API models, per million tokens unless stated:
| Model | Price |
|---|---|
| gemini-embedding-2 | $0.20 per 1M text tokens, $0.10 in Batch |
| gemini-embedding-001 | $0.15, $0.075 in Batch, shuts down 14 May 2028 |
| gemini-nano-banana-2.1 (images) | $1.50 input, $0.0336 per 1K image |
| gemini-3.8-flash-tts | $0.50 text in, $9.00 audio out, doubling on 1 Jan 2027 |
| gemini-3.5-transcribe | $2.00 audio in, $12.00 text out, about $0.005 a minute |
| Gemma 4 | Free tier only, no paid tier on the Gemini API |
Promotional prices and when they end
| Model | Promotional price | Last day | Price after |
|---|---|---|---|
| Gemini 4 Argon | $2.00 / $10.00, cached $0.10 | 30 Nov 2026 | $4.00 / $20.00, cached $0.20 |
| Gemini 3.8 Flash | $0.75 / $3.75, cached $0.075 | 31 Dec 2026 | $1.50 / $7.50, cached $0.15 |
| Gemini 3.6 Flash | $0.75 / $3.75, cached $0.075 | 31 Dec 2026 | $1.50 / $7.50, cached $0.15 |
| Gemini 3.8 Flash TTS | $0.50 / $9.00 | 31 Dec 2026 | $1.00 / $18.00 |
| Gemini 3.8 Flash-Lite TTS | $0.50 / $6.00 | 31 Dec 2026 | $1.00 / $12.00 |
| Gemini 4 Carbon | $2.00 / $10.00 at launch | Not announced | $4.00 / $20.00 |
Batch, Flex and Priority prices double on the same dates. The Argon and Flash promotions also run on Google Cloud's Gemini Enterprise Agent Platform (formerly Vertex AI), where the discount is paid as 50% back on net spend and non-global endpoints cost 10% more. Gemini 4 Carbon, announced on 28 October, is with a small group of security teams for now and isn't on the Gemini API.
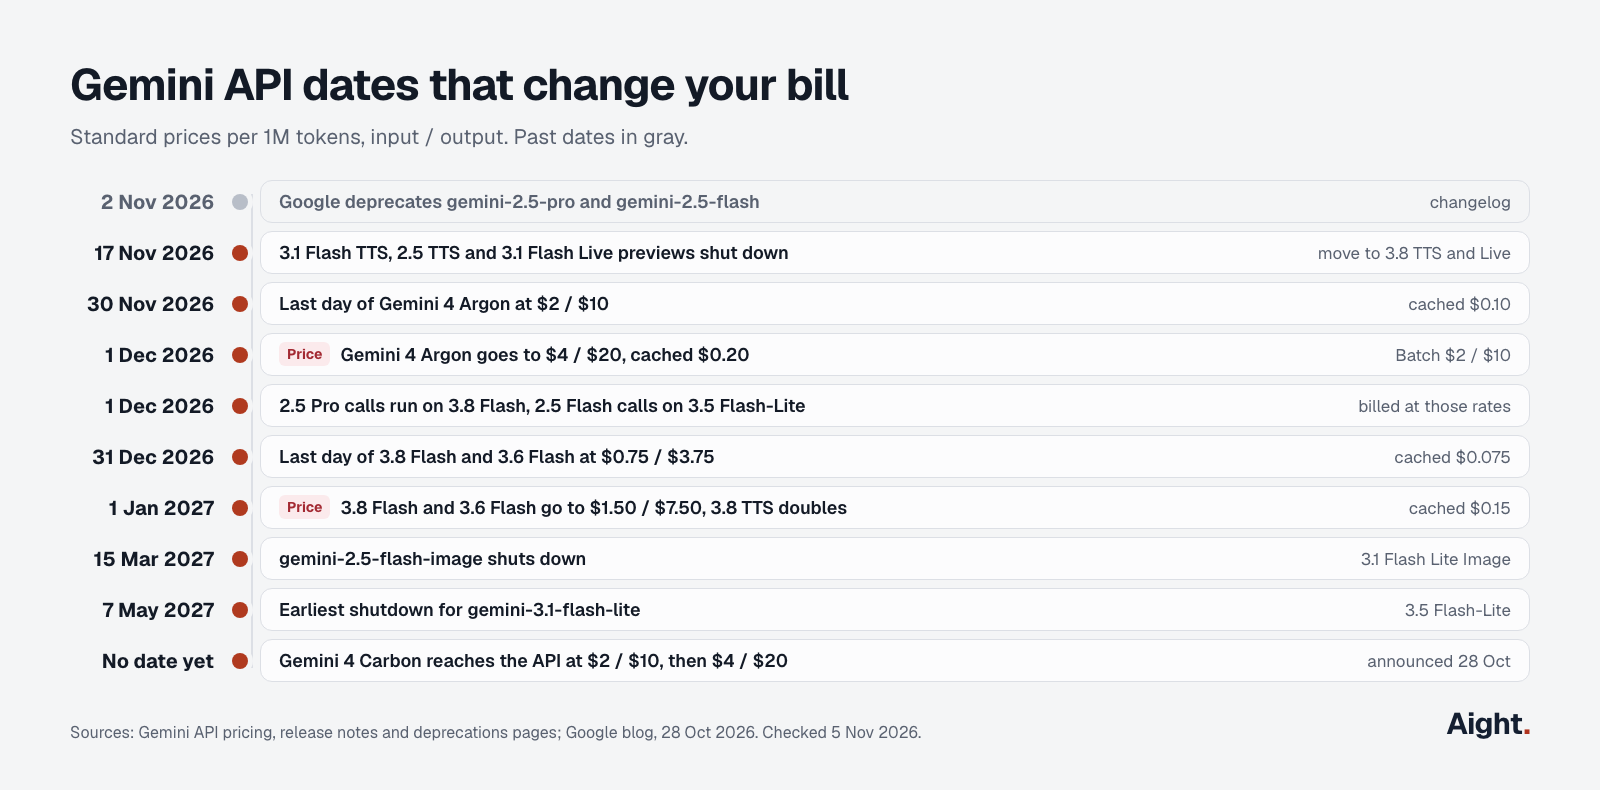
Three shutdowns sit on the same calendar: the 3.1 Flash TTS, 2.5 TTS and 3.1 Flash Live previews on 17 November, gemini-2.5-flash-image on 15 March 2027, and gemini-3.1-flash-lite no earlier than 7 May 2027.
1 December also changes two older models. Google's 2 November release notes say requests to gemini-2.5-pro will run on gemini-3.8-flash and be billed at its rates, and gemini-2.5-flash requests on gemini-3.5-flash-lite. For 2.5 Pro users that cuts the price from $1.25 / $10.00 to $0.75 / $3.75 in December, then $1.50 / $7.50 from 1 January. 2.5 Flash keeps its $0.30 / $2.50. The behavior changes more than the price: 3.8 Flash replaces thinking_budget with thinking_level and drops sampling parameters and prefilled model turns. The Gemini 2.5 migration post covers the code changes.
Gemini Pro API pricing
Gemini Pro API pricing today means Gemini 3.1 Pro Preview: $2.00 / $12.00 per million tokens for prompts up to 200,000 tokens and $4.00 / $18.00 above, with cached input at $0.20 and $0.40. It has no free tier and is still in preview.
The older gemini-2.5-pro ($1.25 / $10.00, $2.50 / $15.00 over 200,000 tokens) serves only existing users and becomes 3.8 Flash on 1 December. Google's most capable model is now Gemini 4 Argon, which doesn't carry the Pro name. Next to 3.1 Pro Preview it costs:
- Less until 30 November ($2 / $10 against $2 / $12), and more from 1 December ($4 / $20).
- The same rate across its whole 1,048,576-token window, where 3.1 Pro Preview doubles input above 200,000 tokens.
- Long outputs: Argon can return up to 1M tokens in one response through long decode, all billed as output. A 500,000-token response costs $5 in output alone now, and $10 from 1 December.
- Cached input at 95% off, through implicit caching only.
Gemini API free tier: models, limits and the catches
The Gemini API free tier costs nothing and needs no billing account, but it covers only the Flash and Flash-Lite models plus embeddings, speech and Gemma 4, with daily limits sized for testing. Google may use free-tier prompts and responses to improve its products, and human reviewers may read them.
| On the free tier | Not on the free tier |
|---|---|
| gemini-3.8-flash, 3.6 Flash, 3.5 Flash-Lite, 3.1 Flash-Lite, 3 Flash Preview | gemini-4-argon, gemini-3.1-pro-preview |
| gemini-embedding-2, gemini-embedding-001 | Every image model, including Nano Banana 2.1 |
| 3.8 Flash TTS, 3.5 Transcribe, 3.8 Live | Gemini Omni Flash (video) and Lyria (music) |
| Gemma 4 (free tier only) | Search grounding on Gemini 3 and newer |
| 2.5 models, for projects that used them before | 2.5 models for new projects |
Google doesn't print free-tier limits in its docs; AI Studio's Rate Limits page shows yours. The rate limits page says limits apply per project, not per API key, and daily quotas reset at midnight Pacific time. Developers on Google's forum report 20 requests a day on 3.8 Flash, and a 3 November quota error for 3.5 Flash-Lite shows limit 500. A support bot with 10,000 requests a day needs a paid project.
The catches:
- Data use. The Gemini API terms say unpaid quota content is used "to provide, improve, and develop Google products". Don't send sensitive data.
- Europe and the UK. If your app serves users in the EEA, Switzerland or the UK, the terms allow only paid services.
- No search. Grounding with Google Search on Gemini 3 and newer returns a 429 on the free tier.
- Verification. Some free projects need mobile device verification and return 403
FREE_TIER_VERIFICATION_REQUIRED; a new key in the same project doesn't get around it. Accounts flagged by Google get a 403 saying the free tier isn't available for the project. - Capacity. Google staff have said 503 errors on free-tier 3.8 Flash come from temporary overload.
- No trial money. Gemini API usage is excluded from the $300 Google Cloud Free Trial for accounts opened after 2 March 2026.
- Billing ends it. Linking billing moves the whole project to the paid tier. Keep a separate unbilled project for free tests.
The free LLM API roundup compares this with other providers' free quotas, and the rate limit post covers handling 429s.
Monthly cost: Gemini vs GPT and Claude
Three workloads at list prices, with the same token counts for every model (real counts differ by tokenizer and thinking level). Gemini's implicit caching charges no write fee; OpenAI's GPT-6 models and Claude bill a cache miss as a cache write at 1.25 times input, applied below wherever caching is on. The method is the one in the LLM API cost per month post.
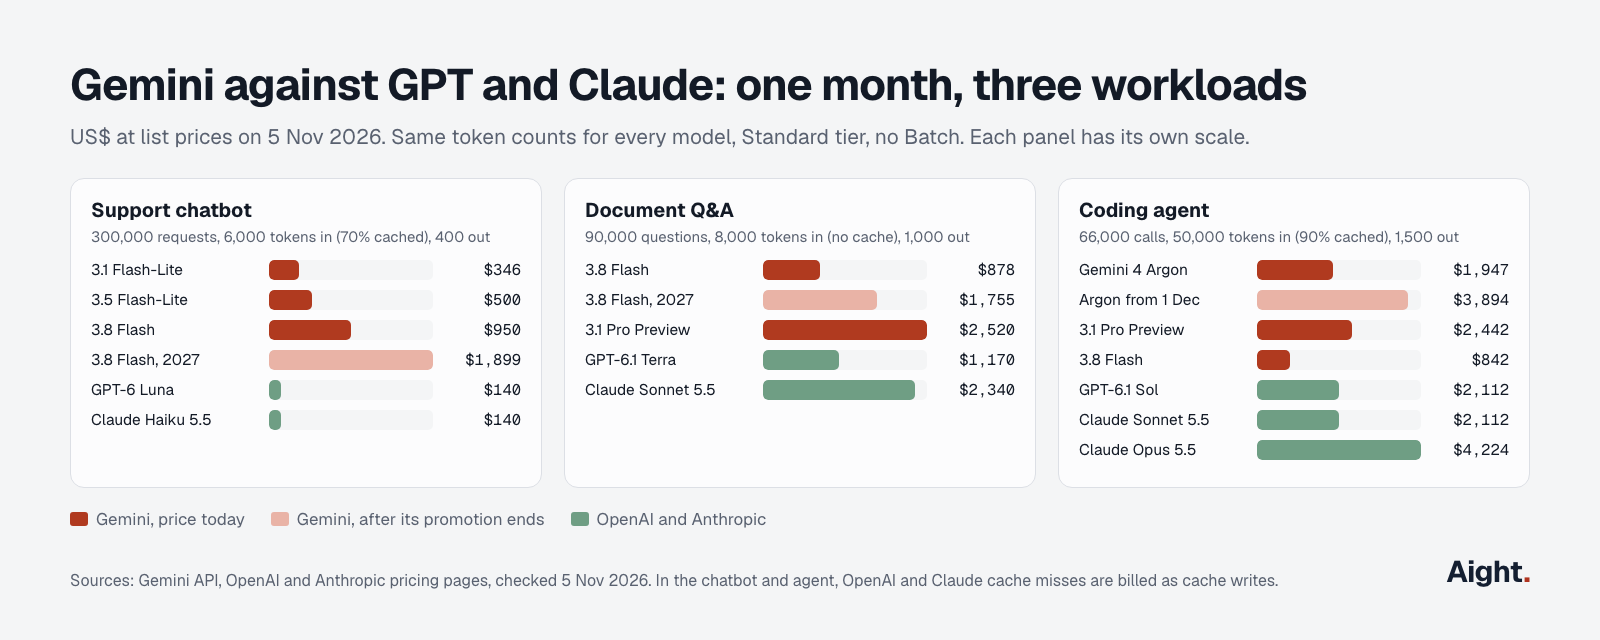
Support chatbot: 300,000 requests a month, 6,000 input tokens each with 70% cache hits, 400 output tokens including thinking.
| Model | Price per 1M (in / out) | Month |
|---|---|---|
| Gemini 3.1 Flash-Lite | $0.25 / $1.50 | $346.50 |
| Gemini 3.5 Flash-Lite | $0.30 / $2.50 | $499.80 |
| Gemini 3.8 Flash, to 31 Dec | $0.75 / $3.75 | $949.50 |
| Gemini 3.8 Flash, from 1 Jan | $1.50 / $7.50 | $1,899.00 |
| GPT-6 Luna | $0.10 / $0.50 | $140.10 |
| Claude Haiku 5.5 | $0.10 / $0.50 | $140.10 |
Google's low-cost models cost 2.5 to 3.6 times GPT-6 Luna and Claude Haiku 5.5 here. Gemini 2.5 Flash-Lite would cost $114.60, but only for projects that already use it. On 3.5 Flash-Lite the month passes Tier 1's $250 cap, so a new account has to reach Tier 2 ($100 paid and 3 days since the first payment) before launch.
Document Q&A: 90,000 questions, 8,000 input tokens each with no cache hits (the retrieved text changes every time), 1,000 output tokens including thinking.
| Model | Price per 1M (in / out) | Month |
|---|---|---|
| Gemini 3.8 Flash, to 31 Dec | $0.75 / $3.75 | $877.50 |
| Gemini 3.8 Flash, from 1 Jan | $1.50 / $7.50 | $1,755.00 |
| Gemini 3.1 Pro Preview | $2.00 / $12.00 | $2,520.00 |
| GPT-6.1 Terra | $1.00 / $5.00 | $1,170.00 |
| Claude Sonnet 5.5 | $2.00 / $10.00 | $2,340.00 |
3.8 Flash costs least until 31 December. From 1 January, GPT-6.1 Terra costs less unless your answers can wait: 3.8 Flash in Batch is $438.75. On OpenAI's default caching mode each new prompt is written to the cache at 1.25 times input, which makes Terra $1,350.00; explicit mode with no breakpoint avoids that.
Coding agent: 66,000 model calls, 50,000 input tokens each with 90% cache hits, 1,500 output tokens including reasoning.
| Model | Price per 1M (in / out) | Month |
|---|---|---|
| Gemini 4 Argon, to 30 Nov | $2.00 / $10.00 | $1,947.00 |
| Gemini 4 Argon, from 1 Dec | $4.00 / $20.00 | $3,894.00 |
| Gemini 3.1 Pro Preview | $2.00 / $12.00 | $2,442.00 |
| Gemini 3.8 Flash, to 31 Dec | $0.75 / $3.75 | $841.50 |
| GPT-6.1 Sol | $2.00 / $10.00 | $2,112.00 |
| Claude Sonnet 5.5 | $2.00 / $10.00 | $2,112.00 |
| Claude Opus 5.5 | $4.00 / $20.00 | $4,224.00 |
Argon has the same list price as Sonnet 5.5 and GPT-6.1 Sol in November but costs $165 less, because its cache misses carry no write fee. From 1 December it lands near Opus 5.5. These are prices, not results; the Claude API pricing post has the Claude side in full.
A cost calculator with the price dates built in
This function picks the price in force on a given day, so a December or January forecast uses the right rate.
from datetime import date

# Gemini API Standard prices, US$ per 1M tokens: (input, output, cached input).
# Each model lists (first day, prices) in date order. Checked 5 Nov 2026.
PRICES = {
    "gemini-4-argon": [(date(2026, 10, 13), (2.00, 10.00, 0.10)),
                       (date(2026, 12, 1), (4.00, 20.00, 0.20))],
    "gemini-3.8-flash": [(date(2026, 9, 2), (0.75, 3.75, 0.075)),
                         (date(2027, 1, 1), (1.50, 7.50, 0.15))],
    "gemini-3.5-flash-lite": [(date(2026, 7, 21), (0.30, 2.50, 0.03))],
    "gemini-3.1-pro-preview": [(date(2026, 2, 19), (2.00, 12.00, 0.20))],  # prompts up to 200K
}


def price_on(model, day):
    current = None
    for start, prices in PRICES[model]:
        if day >= start:
            current = prices
    if current is None:
        raise ValueError(f"no price for {model} on {day}")
    return current


def monthly_cost(model, day, requests, input_tokens, output_tokens, cache_hit=0.0):
    """One month at the prices in force on `day`. Output includes thinking tokens."""
    p_in, p_out, p_cached = price_on(model, day)
    m_in = requests * input_tokens / 1e6  # millions of input tokens
    total = (m_in * (1 - cache_hit) * p_in
             + m_in * cache_hit * p_cached
             + requests * output_tokens / 1e6 * p_out)
    return round(total, 2)


# The coding agent above: 66,000 calls, 50,000 tokens in (90% cached), 1,500 out
for model in ["gemini-4-argon", "gemini-3.8-flash", "gemini-3.1-pro-preview"]:
    row = [monthly_cost(model, d, 66_000, 50_000, 1_500, cache_hit=0.9)
           for d in (date(2026, 11, 15), date(2026, 12, 15), date(2027, 1, 15))]
    print(f"{model:24}", row)
# gemini-4-argon           [1947.0, 3894.0, 3894.0]
# gemini-3.8-flash         [841.5, 841.5, 1683.0]
# gemini-3.1-pro-preview   [2442.0, 2442.0, 2442.0]
Halve the result for Batch or Flex. For real traffic, read the token counts from the response: the Interactions API's usage reports total_input_tokens, total_output_tokens, total_thought_tokens and total_cached_tokens.
Paying Google: prepay, tiers and spend caps
Moving to the paid tier means linking a Cloud Billing account and, for new users, prepaying at least $5 (Google caps prepayment at $5,000). The billing page sets the rules:
- Prepaid balance expires 12 months after purchase and isn't refundable, except when an account switches to Postpay.
- At $0, every key in every project on that billing account stops with HTTP 402. Billing runs about 10 minutes behind, so a balance can go negative; the shortfall comes off your next purchase.
- Requests that fail with a 400 or 500 aren't charged but still count against your quota.
- Project spend caps are experimental and can overshoot by about 10 minutes of usage.
- Since 26 October, new paid projects store Generate Content requests for up to 55 days by default (not used for training). Send
store=falseor turn logging off in AI Studio.
Each tier also caps the month, and the rate limits page caps spend in any rolling 10 minutes:
| Tier | How you get there | Monthly cap | Spend per 10 minutes |
|---|---|---|---|
| Free | Active project | None (no billing) | None |
| Tier 1 | Link billing | $250 | $10 |
| Tier 2 | $100 paid and 3 days | $2,000 | $200 |
| Tier 3 | $1,000 paid and 30 days | $20,000 to $100,000+ | $200 |
At the cap, every project on the billing account pauses until the 1st. Check your forecast against it: the coding agent on Argon from December ($3,894) needs Tier 3 or a cap increase.
What developers report
- "They're doubling the price on December 1st" (Hacker News commenter on the Gemini 4 Argon launch, 13 Oct 2026, link)
- "the free tier limit of 20 RPD is very restrictive" (Google AI developers forum user on Gemini 3.8 Flash, 3 Sep 2026, link)
- A free-tier user reported that the 3.5 Flash-Lite daily quota (limit 500) didn't reset at midnight Pacific on 2 November, after US clocks changed, and recovered about an hour later (Google AI developers forum, 3 Nov 2026, link)
- Google staff confirmed that search grounding isn't on the free tier for Gemini 3 and newer and returns a 429 without billing (Google AI developers forum, 28 Oct 2026, link)
- Google staff said a 403 on a new free project "indicates a flag has been placed on your account" (Google AI developers forum, 2 Nov 2026, link)
Gemini through Aight
Aight is one OpenAI-compatible API for 138 models, Gemini included. Its models page lists Gemini 3.5 Flash-Lite ($0.30 / $2.50), 3.1 Flash-Lite ($0.25 / $1.50) and 3.1 Pro Preview ($2.00 / $12.00, $4.00 / $18.00 over 200,000 tokens) at Google's list prices, served from Google's cloud.
Where Google direct costs less:
- For Gemini 3.8 Flash and Gemini 4 Argon, compare Aight's models page with Google's promotional prices above before routing traffic there.
- Aight documents chat completions, embeddings and the model list, so Batch and Flex discounts are direct-only.
- Aight has no free tier. For testing, Google's free Flash quota costs nothing.
What one Aight key adds is the comparison above: the same prompts through Gemini, GPT-6 Luna and Claude Sonnet 5.5 on one prepaid US dollar balance. Each key can have a monthly cap and a list of allowed models. Unlike Google's prepaid balance, Aight's balance doesn't expire, and unspent paid balance is refundable. Each recharge adds 10% extra, about $0.94 per $1 of list-price usage after the 3% processing fee. The aggregator comparison sets that against other gateways.
FAQ
Is the Gemini API free?
Yes, for the Flash and Flash-Lite models, embeddings, speech models and Gemma 4, within per-project daily limits shown in AI Studio. Argon, 3.1 Pro Preview and the image models need a paid project. Free-tier prompts can be used to improve Google's products.
What is the Gemini API price for Gemini 3.8 Flash?
$0.75 per million input tokens and $3.75 per million output tokens, with cached input at $0.075, through 31 December 2026. From 1 January 2027 it costs $1.50 / $7.50 and $0.15 cached. Batch and Flex cost half.
Does Gemini charge for thinking tokens?
Yes. Google's output price includes thinking tokens, and 3.8 Flash and Argon think at medium by default. Lowering thinking_level is the main way to cut output spend; minimal returns an error on 3.8 Flash.
What happens to Gemini 2.5 Pro pricing on 1 December?
From 1 December 2026, Gemini API requests to gemini-2.5-pro run on Gemini 3.8 Flash and are billed at its rates: $0.75 / $3.75 in December and $1.50 / $7.50 from 1 January. Requests to gemini-2.5-flash run on 3.5 Flash-Lite at the same $0.30 / $2.50.
Does the Google Cloud $300 free trial cover the Gemini API?
No, for accounts opened after 2 March 2026. Older trial balances can still be spent on the Gemini API until they expire.
Sources
- Google, Gemini API: Pricing, Release notes (2 Nov, 26 Oct, 13 Oct, 8 Oct), Deprecations, Rate limits, Billing, Terms, Data logging, Verification
- Google, Gemini API guides: Gemini 4 Argon, What's new in Gemini 3.8, Gemini 3.8 Flash model page, Context caching, Batch API, Flex, Priority, Tokens
- Google Cloud, Gemini Enterprise Agent Platform pricing
- Google blog, Introducing Gemini 4 Carbon, 28 Oct 2026
- Google AI developers forum: 3.8 Flash free tier limit, 3.5 Flash-Lite quota reset, search grounding on the free tier, free tier unavailable, 503 and 429 on the free tier
- Hacker News, Gemini 4 Argon launch thread
- OpenAI, Pricing and Prompt caching
- Anthropic, Pricing
- Aight, Models and pricing, API reference, Refund policy
Checked on 5 November 2026. Updated 17 November 2026: Aight's current model list, and where Google documents the spend-rate limit.