The free LLM API tiers worth using on 5 November 2026 are Google's Gemini API (Gemini 3.8 Flash, 3.5 Flash-Lite and Gemma 4), Groq (gpt-oss-120b and Qwen3.8 27B), Mistral's Free mode, Cloudflare Workers AI (10,000 Neurons a day), OpenRouter's 12 free text models and Vercel AI Gateway ($5 of usage a month). None covers real traffic: without paying anything, the most generous allows about 500 average requests a day, and the one with the strongest model, Google's, can use your prompts for training.
Older lists are out of date: GitHub Models shut down on 30 July 2026, Cerebras now offers a 30-day $5 trial that needs a payment method, and Hugging Face gives free accounts no inference allowance. Every limit below was read on the provider's own page on 5 November 2026, except Groq's: its site refused the network used for this post, so its figures come from the Internet Archive's copy of its rate-limits page dated 30 October.
Every free LLM API tier at a glance
| Provider | Free models (examples) | Free limit | Trains on your prompts? | Main catch |
|---|---|---|---|---|
| Google Gemini API | Gemini 3.8 Flash, 3.5 Flash-Lite, Gemma 4, embeddings | Shown only in AI Studio; developers report 20 requests a day on 3.8 Flash, 500 on Flash-Lite | Yes, and human reviewers may read it (not in the EEA, Switzerland, UK) | Can't serve users in the EEA, Switzerland or UK |
| Groq | gpt-oss-120b, gpt-oss-20b, Qwen3.8 27B, Whisper | 30 a minute, 1,000 a day, 8,000 tokens a minute, 200,000 tokens a day | No retention by default | Token caps bind first |
| Mistral Free mode | Mistral Small 4 and others | Shown only on your console's Limits page | Yes, unless you opt out | No published numbers |
| Cloudflare Workers AI | gpt-oss-120b, Gemma 4 26B, Llama 3.3 70B | 10,000 Neurons a day | No | DeepSeek, Kimi and GLM-5 need the paid plan |
OpenRouter :free | 12 text models, such as Gemma 4 31B | 20 a minute; 50 a day, or 1,000 after buying $10 | Depends on the host; NVIDIA-hosted ones may | The free list changes often |
| Vercel AI Gateway | A subset of its catalog | $5 of usage a month | Varies by model | Any purchase ends it |
| Cohere trial key | Command A, Command R+ | 20 a minute, 1,000 calls a month | Not stated | For tests and proofs of concept |
| NVIDIA build.nvidia.com | Hosted NIM endpoints | Not published | Yes, per its trial terms | Trial and testing only |
| OpenAI data sharing | gpt-6-luna, gpt-5.6-luna and others | 250,000 to 10 million tokens a day | Yes, that's the exchange | Needs a paid account with a positive balance |
For a standard request of 2,000 input and 500 output tokens, this is how many each free tier allows in a day:
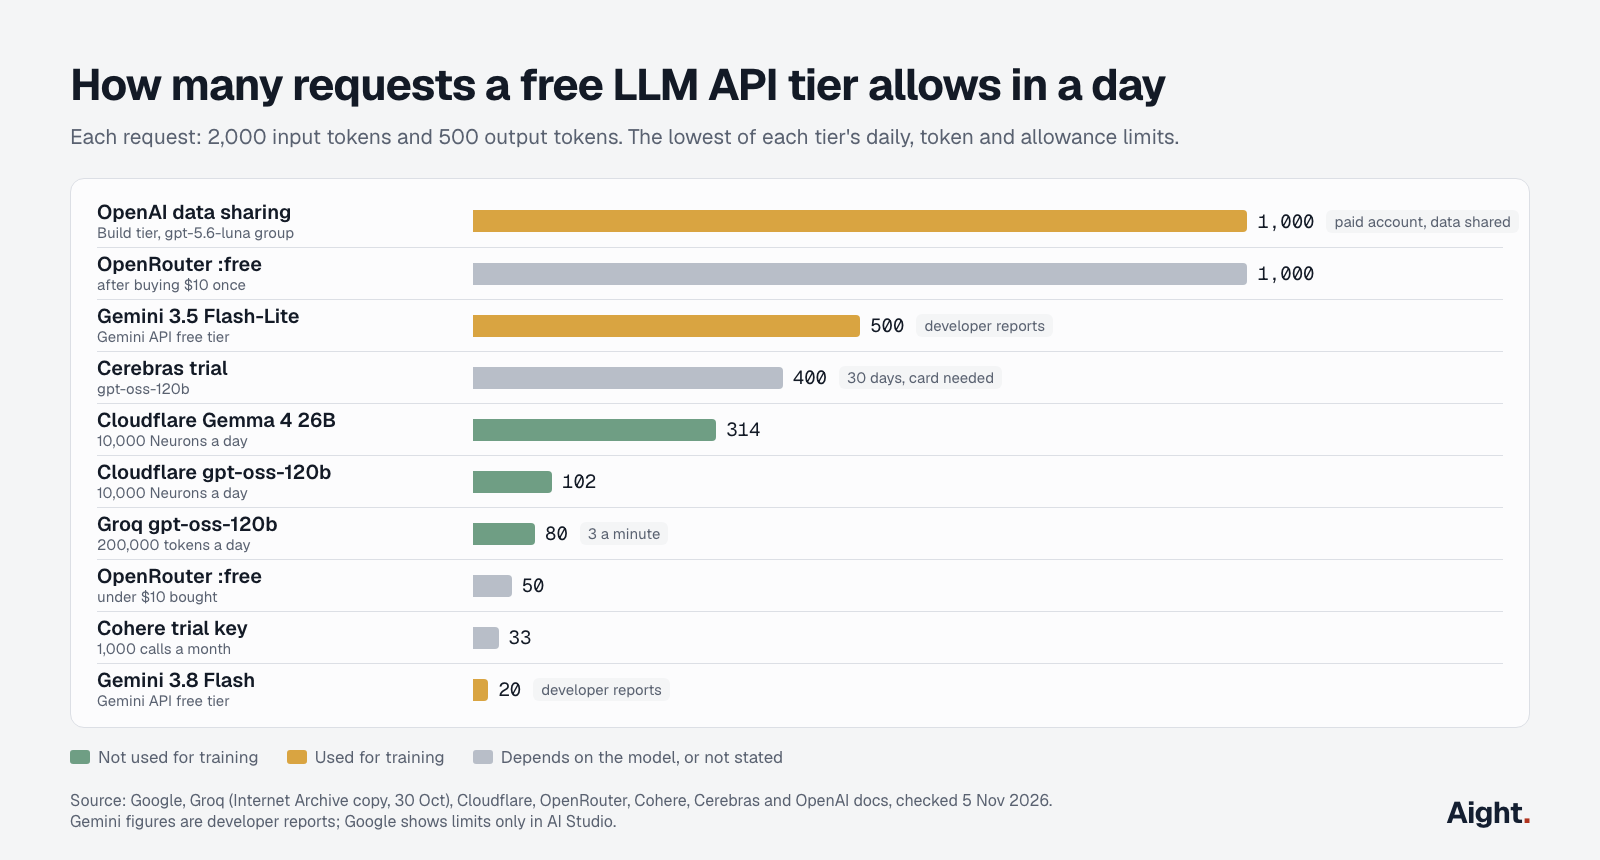
| Free tier | Binding limit | Standard requests a day |
|---|---|---|
| Gemini 3.8 Flash | 20 requests a day (developer reports) | 20 |
| Cohere trial key | 1,000 calls a month | About 33 |
OpenRouter :free, under $10 bought | 50 requests a day | 50 |
| Groq gpt-oss-120b | 200,000 tokens a day | 80 |
| Cloudflare gpt-oss-120b | 97.7 Neurons per request | 102 |
| Cloudflare Gemma 4 26B A4B | 31.8 Neurons per request | 314 |
| Cerebras trial (30 days) | 1 million tokens a day | 400 |
| Gemini 3.5 Flash-Lite | 500 requests a day (developer reports) | 500 |
OpenRouter :free, $10 or more bought | 1,000 requests a day | 1,000 |
| OpenAI data sharing, Build tier, small-model group | 2.5 million tokens a day | 1,000 |
What each free tier gives you
Google Gemini API
Google's pricing page puts Gemini 3.8 Flash, 3.5 Flash-Lite, 3.1 Flash-Lite, Gemma 4, the embedding models, the 3.8 TTS models and Gemini 3.5 Transcribe on the free tier. Gemini 4 Argon, 3.1 Pro Preview and the image models aren't on it.
Google no longer publishes free-tier numbers. Its rate-limits page says limits apply per project, not per key, reset at midnight Pacific, and "can be viewed in Google AI Studio." Developers on Google's forum report 20 requests a day for 3.8 Flash and 500 for Flash-Lite. Some free projects must pass mobile device verification first, or the API returns 403 FREE_TIER_VERIFICATION_REQUIRED. Search grounding isn't available on the free tier for Gemini 3 models, and since March 2026 Google Cloud's $300 trial doesn't cover the Gemini API. Paid prices are in the Gemini API pricing post.
Groq
Groq's free plan covers gpt-oss-120b, gpt-oss-20b and Qwen3.8 27B (a preview model) at 30 requests a minute, 1,000 a day, 8,000 tokens a minute and 200,000 tokens a day. The token caps bind first: three standard requests a minute, 80 a day. Whisper Large V3 Turbo allows 28,800 audio seconds a day, eight hours of audio.
Groq lists gpt-oss-120b at 500 tokens a second. Its Llama chat models are now Enterprise only, so lists that call Llama 3.3 70B free on Groq are out of date. Groq doesn't retain inference data by default, but may log it for up to 30 days to troubleshoot errors or investigate abuse unless you opt out in Data Controls.
Mistral
Mistral's Free mode needs no payment card, and its limits are whatever your console's Limits page shows, per model. Its help center says Free mode inputs and outputs may be used for training; turn that off in the Admin panel under Privacy, Anonymous improvement data. Zero data retention is for paid plans only.
Cloudflare Workers AI
Every Cloudflare account gets 10,000 Neurons a day at no charge, resetting at 00:00 UTC. On the Workers Free plan, requests fail once they're used up; on Workers Paid, extra Neurons cost $0.011 per 1,000. gpt-oss-120b uses 31,818 Neurons per million input tokens and 68,182 per million output tokens, so a standard request takes 97.7 Neurons and the day holds 102 of them. Gemma 4 26B A4B fits 314.
Cloudflare's data page is the clearest of any free tier: no training on Workers AI content and no retention of standard inference data. Kimi K2.6, GLM-5.3, DeepSeek V4.1 Flash and a few others need the paid plan.
OpenRouter, Vercel, Cohere, NVIDIA and OpenAI
- OpenRouter allows 20 requests a minute and 50 a day on
:freemodels, or 1,000 a day once you've bought $10 of usage. It listed 12 free text models on 5 November, and the free Nemotron models run on NVIDIA's endpoint, which OpenRouter marks as one that may train on prompts. The OpenRouter free models post covers each one. - Vercel AI Gateway includes $5 of usage a month on a subset of models. Buying any usage moves the team to the paid tier and ends the free amount.
- Cohere trial keys get 20 chat requests a minute per model and 1,000 calls a month.
- NVIDIA gives Developer Program members free hosted endpoints "for prototyping, research, development and testing purposes only," with no published rate limit. Its API trial terms let it use your inputs and outputs to improve its products, AI models included.
- OpenAI has no free tier, but eligible paid accounts that share traffic for training get free daily tokens: 250,000 on the large-model group (gpt-6-luna, gpt-6.1-sol) and 2.5 million on the small-model group (gpt-5.6-luna and others) at the Build tier, and 1 million and 10 million at Launch and Grow.
What's no longer free
- GitHub Models was retired on 30 July 2026, API included, for every customer. GitHub points to Microsoft Foundry and Copilot instead.
- Cerebras's Developer tier gives a one-time $5 trial balance once you add a payment method, expiring after 30 days, at 5 requests a minute and 1 million tokens a day. At $0.35 / $0.75 on gpt-oss-120b, $5 covers 4,651 standard requests: about 12 days at the daily cap.
- Hugging Face's Inference Providers pricing lists the monthly allowance for free users as "None." PRO ($9 a month) includes $2.00 of inference.
The catches: training, limits and regions
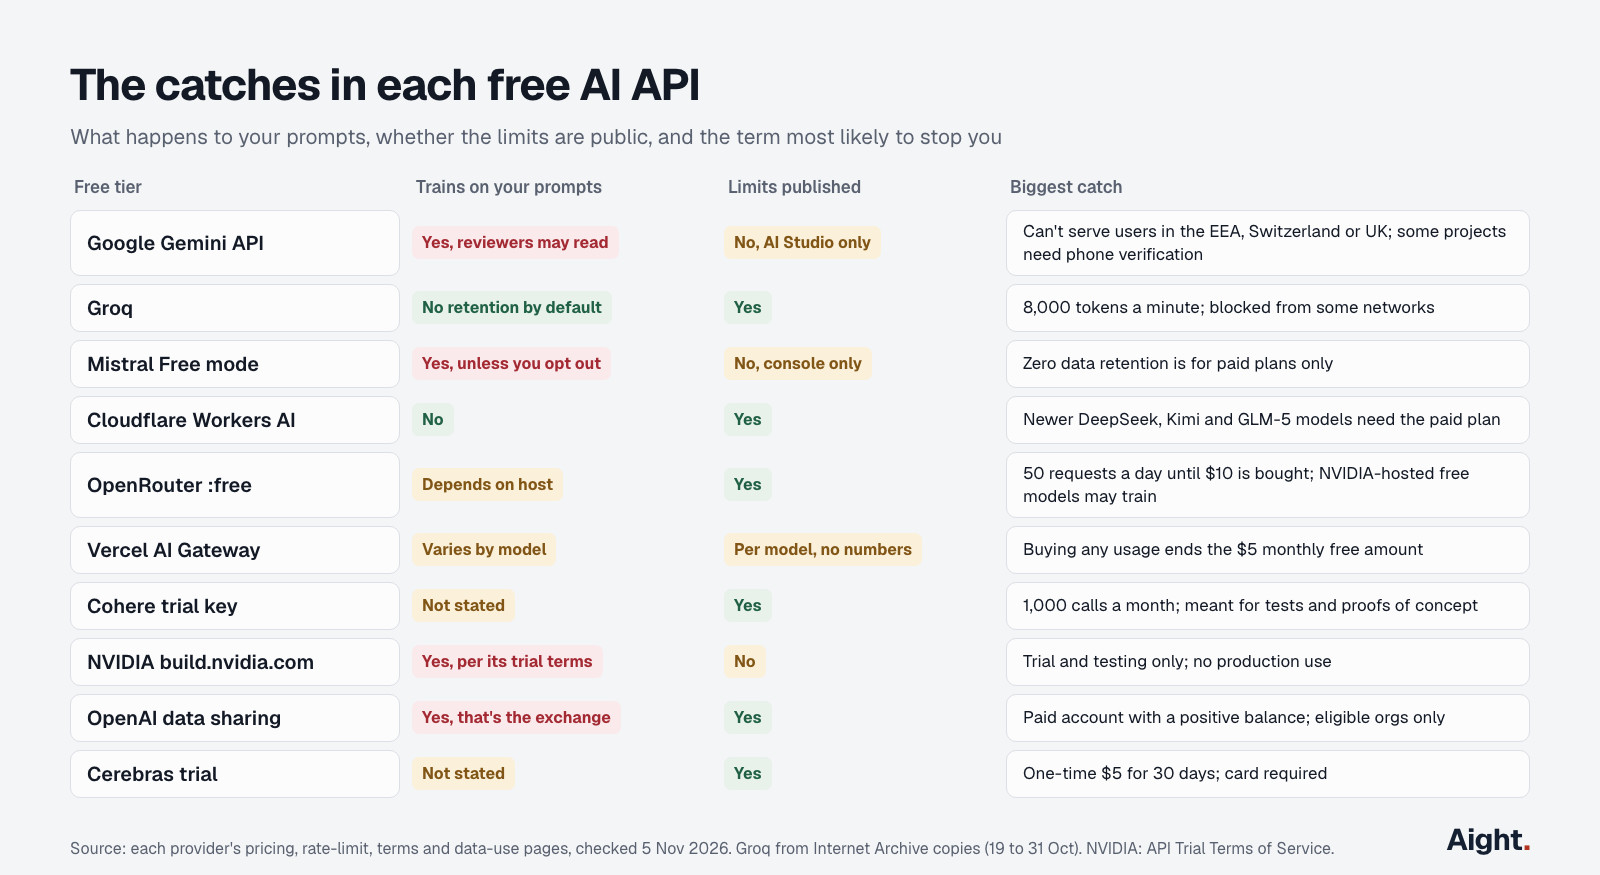
Your prompts may train the model
On Google's free tier, the Gemini API terms say Google uses what you send "to provide, improve, and develop Google products," that human reviewers may read it, and: "Do not submit sensitive, confidential, or personal information to the Unpaid Services." Mistral's Free mode trains unless you opt out, NVIDIA's trial terms allow it, and OpenAI's free tokens exist only for traffic you share for training. Cloudflare says it doesn't train on Workers AI content, and Groq doesn't keep inference data by default. If your test data is real customer data, that narrows the free options to those two, or a model on your own machine. The zero data retention guide covers the paid side.
Daily quotas behave differently from minute limits
A per-minute 429 clears in seconds; a per-day one lasts until the reset. Many clients retry both the same way: the OpenAI SDK retries a 429 twice by default, and one eval framework kept retrying a Gemini daily quota for over ten minutes. Gemini counts per project, so a second key in the same project adds no quota, and no free tier carries a service guarantee. The rate limit exceeded guide covers how to read each provider's 429.
Where you are and who your users are
Google's terms allow only paid services when your app serves users in the EEA, Switzerland or the UK, and free-tier data there gets paid-tier privacy terms. The Gemini API works only in its listed regions. Groq refused every request from the network used for this post, so test reachability from the place your code will run.
Best free LLM for each job
Scores are the Artificial Analysis Intelligence Index v5.0.1 at each model's highest listed effort. For comparison, paid GPT-6 Luna scores 21 and Claude Haiku 5.5 scores 30 at high effort. gpt-oss-120b and Gemma 4 aren't scored on this version yet.
| Job | Free AI model | Where | Why | Catch |
|---|---|---|---|---|
| Best quality | Gemini 3.8 Flash | Gemini API | Index 31, the highest on any no-cost tier | About 20 requests a day; Google may train |
| High-volume extraction | Gemini 3.5 Flash-Lite | Gemini API | About 500 requests a day | Index 12; Google may train |
| Private data | gpt-oss-120b or Gemma 4 26B | Cloudflare | No training or retention | 102 or 314 requests a day |
| Lowest latency | gpt-oss-120b | Groq | Listed at 500 tokens a second | 8,000 tokens a minute |
| Coding experiments | Qwen3.8 27B | Groq | Index 20, the best-scoring open model on a free tier | Preview model |
| Long documents | Nemotron 3.5 Super VL | OpenRouter :free | 1 million tokens of context | Index 14; NVIDIA's host may train |
| Transcription | whisper-large-v3-turbo | Groq | Eight hours of audio a day | 20 requests a minute |
| Embeddings | bge-m3 | Cloudflare | About 9.3 million tokens a day | Shares the 10,000 Neurons |
| No quota at all | Gemma 4 | Your machine, with Ollama | Nothing leaves the machine | Your RAM and GPU |
Gemini 3.8 Flash thinks at length: at paid prices it spent $7.77 per Artificial Analysis task, against $0.07 for GPT-6 Luna (high). Free, those tokens cost nothing; paid, it gets expensive. The best LLM API guide compares the paid options.
When paying costs less than a free tier
Paid prices for this kind of traffic are low enough that a free tier's hidden costs often outweigh them. At list prices:
| Model | Price per 1M tokens, in / out | 1,000 requests | 30 days at 1,000 a day |
|---|---|---|---|
| GPT-6 Luna (OpenAI) | $0.10 / $0.50 | $0.45 | $13.50 |
| Claude Haiku 5.5 (Anthropic) | $0.10 / $0.50 | $0.45 | $13.50 |
| gpt-oss-120b (Groq Developer plan) | $0.15 / $0.60 | $0.60 | $18.00 |
| DeepSeek V4.1 Flash, off-peak | $0.15 / $0.60 | $0.60 | $18.00 |
| gpt-oss-120b (Cloudflare) | $0.35 / $0.75 | $1.08 | $32.25 |
| Gemini 3.5 Flash-Lite | $0.30 / $2.50 | $1.85 | $55.50 |
| Gemini 3.8 Flash, to 31 December | $0.75 / $3.75 | $3.38 | $101.25 |
Reasoning tokens are billed as output, so treat 500 output tokens as a floor. Against those numbers, the free tier's costs:
- To test with real user data, Gemini's free tier is out, Mistral's needs the opt-out first, and OpenAI's data-sharing offer is out by design.
- A fallback chain, quota-aware retries and daily monitoring take hours to build and keep working. At $100 an hour, two hours equal almost 15 months of 1,000 requests a day on GPT-6 Luna.
- Groq's 8,000 tokens a minute is three requests; Cerebras's trial allows five a minute. A demo with ten simultaneous users fails on either.
- No free tier offers a service guarantee, NVIDIA's terms rule out production, and Gemini's rule out users in the EEA, Switzerland and the UK.
A workable rule: stay free while one developer prototypes with made-up data at a few hundred requests a day. Pay as soon as real user data, a second concurrent user, or users in Europe enter the picture. At 1,000 standard requests a day, that's $13.50 to $18 a month on the lowest-priced models above. The OpenAI API alternatives post compares paid providers job by job.
A fallback chain across free tiers
All three providers below accept the OpenAI SDK. This uses openai 3.45.0 (released 4 November), tries the tiers that don't train on prompts first, and moves on when one runs out of quota:
import os
from openai import OpenAI, APIStatusError, APIConnectionError

ACCOUNT = os.environ.get("CLOUDFLARE_ACCOUNT_ID", "")

# (name, base URL, key variable, model). Free tiers that don't train on prompts first.
FREE_TIERS = [
    ("groq", "https://api.groq.com/openai/v1", "GROQ_API_KEY", "openai/gpt-oss-120b"),
    ("cloudflare", f"https://api.cloudflare.com/client/v4/accounts/{ACCOUNT}/ai/v1",
     "CLOUDFLARE_API_TOKEN", "@cf/openai/gpt-oss-120b"),
    ("gemini", "https://generativelanguage.googleapis.com/v1beta/openai/",
     "GEMINI_API_KEY", "gemini-3.5-flash-lite"),  # free tier: Google may train on prompts
]


def ask(messages):
    skipped = []
    for name, base_url, key_var, model in FREE_TIERS:
        key = os.environ.get(key_var)
        if not key:
            continue
        # max_retries=0: a per-day quota 429 won't clear in seconds, so move on
        client = OpenAI(base_url=base_url, api_key=key, max_retries=0, timeout=60)
        try:
            r = client.chat.completions.create(model=model, messages=messages)
            return name, r.choices[0].message.content
        except APIStatusError as e:
            if e.status_code == 429 or e.status_code >= 500:
                skipped.append(f"{name} {e.status_code}")
                continue  # out of quota or overloaded: try the next free tier
            raise  # 400, 401, 403: a bad key, model or request; fix it, don't hide it
        except APIConnectionError:
            skipped.append(f"{name} unreachable")
    raise RuntimeError("no free tier answered: " + ", ".join(skipped))


if __name__ == "__main__":
    print(ask([{"role": "user", "content": "Classify this ticket: refund not received."}]))
The base URLs come from each provider's OpenAI compatibility docs. Tested offline with a mocked transport, a 429 from Groq falls through to Cloudflare and a 401 is raised. Gemini answers a bad key with 400 INVALID_ARGUMENT, not 401, and an unverified free project with 403; both are raised on purpose, since skipping them would hide a setup problem.
What developers report about free tiers
- "the free tier limit of 20 RPD is very restrictive" (Google AI Developers Forum user on Gemini 3.8 Flash, 3 Sep 2026, link)
- An eval run on a free-tier Gemini key hit the per-day quota (
GenerateRequestsPerDayPerProjectPerModel-FreeTier) and the framework kept retrying for over ten minutes, because it treated a daily limit like a per-minute one (inspect_ai GitHub issue #5526, 23 Sep 2026, link) - A developer's 500-request free quota on gemini-3.5-flash-lite refused requests after midnight Pacific on 2 November and worked again by 09:11 UTC (Google AI Developers Forum, 3 Nov 2026, link)
- On free-tier projects marked "Unavailable", a Google staff member said the 403 "indicates a flag has been placed on your account" (Google AI Developers Forum, 2 Nov 2026, link)
- A Hacker News commenter running a coding harness on a free OpenRouter model saw it fail to use the correct tool-call syntax until told to check the format (Hacker News, 29 Oct 2026, link)
Where Aight fits
Aight has no free tier, so it isn't in the tables above. It fits the step after, when a free tier's limits or data terms stop working: one OpenAI-compatible API for 138 models, paid from a prepaid US dollar balance with no subscription. Outside India a recharge starts at $5 plus 3% processing, and every recharge adds 10% extra balance.
What that changes for the problems above:
- Prompts and outputs aren't stored, and Aight's privacy policy says they are never used to train models.
- gpt-oss-120b, the model Groq, Cloudflare and Cerebras offer free, is listed at $0.15 / $0.60 as
gpt-oss-120b-aws, running on AWS Bedrock in the United States: $0.60 per 1,000 standard requests, or about $0.56 counting the 10% extra and the 3% fee. - Each key can carry a monthly cap, an expiry date and a list of allowed models, so a prototype can't spend past its limit.
Where another route is better: under a few hundred requests a day with made-up data, the free tiers cost nothing. Groq's paid gpt-oss-120b and DeepSeek V4.1 Flash off-peak cost $0.60 per 1,000 direct, and GPT-6 Luna costs $0.45, so a single-model app may be simpler on one direct account. Prices for every model are on the models page.
FAQ
Is there a completely free LLM API?
Yes, within limits. Google's Gemini API, Groq, Mistral's Free mode, Cloudflare Workers AI and OpenRouter's :free models cost nothing up to their quotas. The only option with no quota is running an open model such as Gemma 4 on your own hardware.
What is the best free LLM API?
For model quality, Google's free tier with Gemini 3.8 Flash, which scores 31 on Artificial Analysis, but developers report about 20 requests a day and Google may train on your prompts. For private data, Cloudflare Workers AI; for speed, Groq.
Is the Gemini API free?
Partly. Gemini 3.8 Flash, 3.5 Flash-Lite, 3.1 Flash-Lite, Gemma 4 and the embedding models have a free tier, while Gemini 4 Argon, 3.1 Pro Preview and the image models are paid only. Free-tier prompts may be used to improve Google's products, and your limits are shown only in AI Studio.
Do free AI APIs train on your data?
Some do. Google's free tier (outside the EEA, Switzerland and the UK), Mistral's Free mode and NVIDIA's trial endpoints can use prompts for training, though Mistral lets you opt out. Cloudflare says it doesn't train on Workers AI content, and Groq doesn't retain inference data by default.
Can you use a free LLM API in production?
Check the terms first. NVIDIA's free endpoints are for prototyping and testing only, Cohere's trial keys are for tests and proofs of concept, and Gemini's free tier can't serve users in the EEA, Switzerland or the UK. Elsewhere there's still no service guarantee.
Is GitHub Models still free?
No. GitHub retired GitHub Models on 30 July 2026, including the API, for every customer. GitHub points developers to Microsoft Foundry or GitHub Copilot instead.
Sources
- Google: Gemini API pricing, Rate limits, Billing, Project verification, Additional terms, Available regions, OpenAI compatibility
- Google AI Developers Forum: 3.8 Flash free tier thread, Flash-Lite quota reset thread, free tier unavailable thread
- Groq (Internet Archive copies): Rate limits, 30 Oct 2026, Models, 31 Oct 2026, Your data, 19 Oct 2026
- Mistral: Create an API key, Usage and limits, Training data FAQ, Training opt-out, Zero data retention, Models, Pricing
- Cloudflare: Workers AI pricing, Data usage, Limits, OpenAI compatibility
- OpenRouter: Limits, Models API, Nemotron 3.5 Super VL endpoints, Provider logging, Free LLM APIs compared
- Vercel: AI Gateway pricing
- Cohere: Rate limits, Pricing
- NVIDIA: NIM general FAQ, API Trial Terms of Service
- OpenAI: Data sharing and complimentary tokens, Rate limits and usage tiers, Pricing, openai on PyPI
- Cerebras: Pricing, Rate limits
- GitHub: GitHub Models is now retired, inspect_ai issue #5526
- Hugging Face: Inference Providers pricing, Pricing
- Anthropic: Pricing
- DeepSeek: Models and pricing
- Artificial Analysis: LLM leaderboard
- Hacker News: comment on a free OpenRouter model in a coding harness
- Aight: Models and pricing, Privacy policy, Docs
Checked on 5 November 2026. Updated 17 November 2026: Aight's current model list.