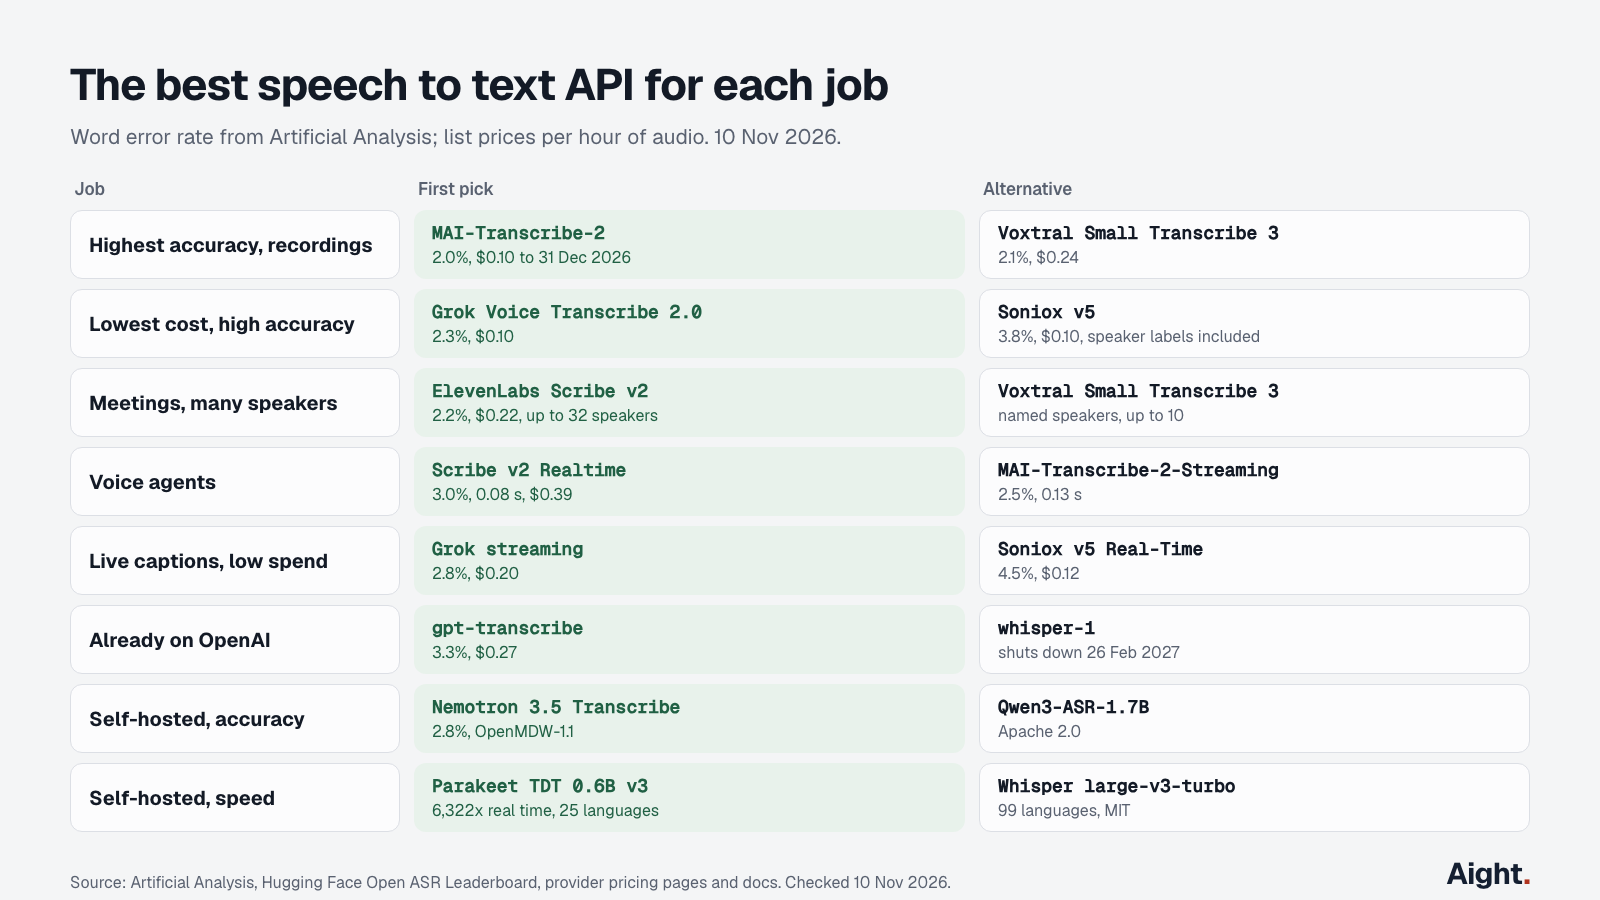
The best speech to text API for recorded audio in November 2026 is a three-way tie at the top: Microsoft's MAI-Transcribe-2 (2.0% word error rate), Mistral's Voxtral Small Transcribe 3 (2.1%) and ElevenLabs Scribe v2 (2.2%) lead the Artificial Analysis benchmark, at $0.10 to $0.24 an hour of audio. For the lowest price at near-top accuracy, xAI's Grok Voice Transcribe 2.0 scores 2.3% for $0.10 an hour. For live audio, MAI-Transcribe-2-Streaming (2.5%) and ElevenLabs Scribe v2 Realtime (3.0%, 0.08 seconds to a final transcript) lead.
The gaps between the top ten are a fraction of a percentage point, so the right pick usually comes down to price, speed, speaker labels and languages. Below are the current rankings with dates, the price per hour and per 1,000 hours, latency for live audio, which APIs label speakers, the best open-weight models to run yourself, and a pick for each job. Benchmark scores were read from Artificial Analysis and the Hugging Face Open ASR Leaderboard on 10 November 2026; prices are each provider's pay-as-you-go list price in US dollars on the same day.
Best speech to text APIs at a glance
- Highest accuracy on recordings: MAI-Transcribe-2 (2.0%), at a $0.10 an hour launch price that runs to the end of 2026.
- Highest accuracy with stable pricing: Voxtral Small Transcribe 3 (2.1%, $0.24 an hour) or Voxtral Mini Transcribe 3 (2.2%, $0.21).
- Many languages and speakers: ElevenLabs Scribe v2 (2.2%, $0.22 an hour, 90+ languages, up to 32 speakers).
- Lowest price at high accuracy: Grok Voice Transcribe 2.0 (2.3%, $0.10 an hour, speaker labels by flag).
- Voice agents and live captions: Scribe v2 Realtime (3.0%, 0.08 s) or Grok streaming (2.8%, $0.20 an hour).
- Already on Google: Gemini 3.5 Transcribe (2.6%, about $0.31 an hour, free tier).
- Run it yourself: NVIDIA Nemotron 3.5 Transcribe (2.8% on Artificial Analysis, OpenMDW license) or Parakeet TDT 0.6B v3 for raw speed.
How speech to text models are benchmarked
Word error rate (WER) is the share of words a model gets wrong: substitutions, deletions and insertions divided by the words in the reference transcript. Lower is better, and 2% means about one wrong word in 50.
Two public leaderboards matter, and their numbers can't be compared with each other:
- Artificial Analysis (AA-WER v2) tests about 8 hours of audio from three sets: AA-AgentTalk (50%), VoxPopuli-Cleaned-AA (25%) and Earnings22-Cleaned-AA (25%). It covers both APIs and open models served by an API host, lists each one's price, and runs a separate streaming benchmark that also times the final transcript.
- The Open ASR Leaderboard on Hugging Face averages nine English sets, including AMI meetings, Earnings22, GigaSpeech, SPGISpeech and two private sets, plus a seven-language multilingual board. It reports RTFx (seconds of audio processed per second of compute) for models it runs itself. Version 1.15.0, dated 6 November 2026, is the one used here.
Its harder meeting and noisy sets push every score up: Scribe v2 averages 5.93% there against 2.2% on Artificial Analysis. Use each board to rank models, not to predict your own error rate.
Speech to text models ranked by accuracy
These are the best speech to text models on Artificial Analysis for recorded files on 10 November 2026, with each provider's list price.
| Rank | Model | AA-WER | Per hour | 1,000 hours | Speed (x real time) |
|---|---|---|---|---|---|
| 1 | Alibaba Fun-Realtime-ASR (preview) | 1.7% | $0.17 (AA's listed price) | $169 | 21x |
| 2 | Microsoft MAI-Transcribe-2 | 2.0% | $0.10 to 31 Dec 2026 | $100 | 312x |
| 3 | Mistral Voxtral Small Transcribe 3 | 2.1% | $0.24 | $240 | 67x |
| 4 | ElevenLabs Scribe v2 | 2.2% | $0.22 | $220 | 80x |
| 5 | Mistral Voxtral Mini Transcribe 3 | 2.2% | $0.21 | $210 | 78x |
| 6 | xAI Grok Voice Transcribe 2.0 | 2.3% | $0.10 | $100 | 193x |
| 9 | Google Gemini 3.5 Transcribe | 2.6% | $0.31 | $306 | 92x |
| 12 | NVIDIA Nemotron 3.5 Transcribe (open) | 2.8% | self-hosted | ||
| 16 | AssemblyAI Universal-3.5 Pro | 3.0% | $0.21 | $210 | 101x |
| 19 | OpenAI gpt-transcribe | 3.3% | $0.27 | $270 | 46x |
| 28 | Soniox v5 Async | 3.8% | $0.10 | $100 | 47x |
| Speechmatics Melia 1 | 4.9% | $0.24 | $240 | 171x | |
| Deepgram Nova-3 | 5.2% | $0.26 | $258 | 556x |
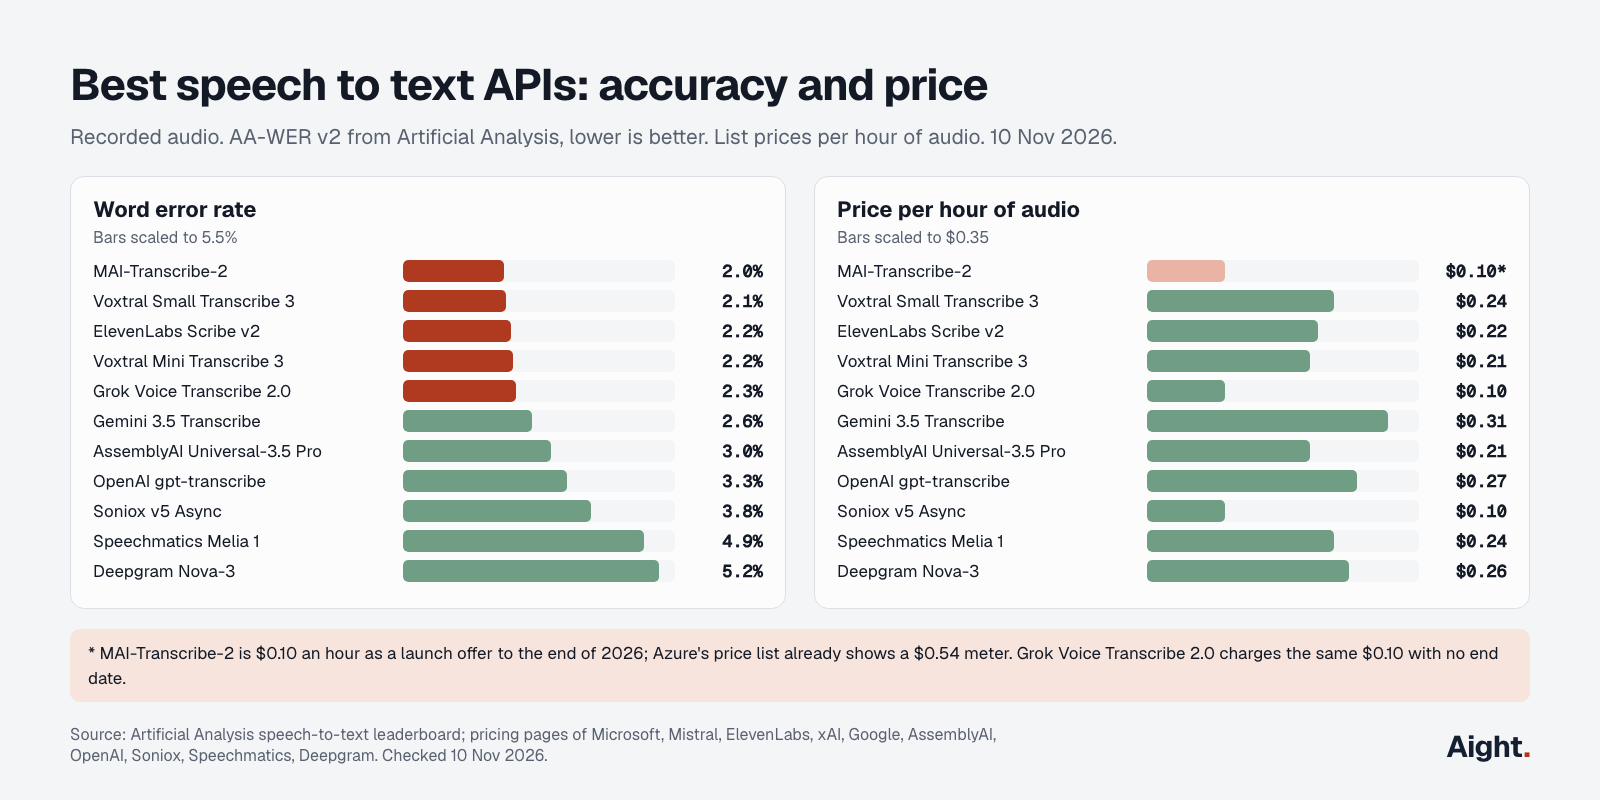
Notes on the ranking:
- Alibaba's Fun-Realtime-ASR tops the board but is a preview model with no release date on Artificial Analysis, so it is listed for reference rather than recommended for production.
- Microsoft's launch post (3 September 2026) prices MAI-Transcribe-2 at $0.10 an hour "as a limited-time offer until the end of the year." Microsoft hasn't published the 2027 price; the Azure retail prices API already shows a $0.54 an hour meter for the model, effective 1 October 2026. Plan your costs on $0.54 until Microsoft says otherwise.
- Nemotron 3.5 Transcribe scores 2.8% on its best-scoring host and 3.4% on DeepInfra's at $2.00 per 1,000 minutes ($0.12 an hour). Hosts can differ.
- Gemini 3.5 Transcribe is billed per token. At Google's estimate of 25 audio tokens a second and 175 text tokens a minute, $2.00 / $12.00 per million comes to about $0.0051 a minute.
- Speed is the median multiple of real time: at 312x, MAI-Transcribe-2 returns an hour of audio in about 12 seconds; at 46x,
gpt-transcribetakes about 78 seconds.
On the Open ASR Leaderboard's English board the order among APIs is different: Zoom Scribe v2.1 Pro (4.87%), Otter (5.21%), Microsoft's azure-speech-09-2026 (5.55%) and Scribe v2 (5.93%) lead, with AssemblyAI Universal-3.5 Pro at 6.21% and gpt-transcribe at 6.80%. On its multilingual board (German, French, Italian, Spanish, Portuguese, Hindi and Dutch), Microsoft (3.47%) and Scribe v2 (3.57%) lead, ahead of gpt-transcribe (4.36%).
Price per hour of the best speech to text APIs
Most providers now charge $0.10 to $0.30 an hour for recorded audio, and live audio costs about twice as much. Prices checked on each provider's page on 10 November 2026:
| Provider and model | Recorded, per hour | Live, per hour | Free to start |
|---|---|---|---|
| xAI Grok Voice Transcribe 2.0 | $0.10 | $0.20 | |
| Soniox v5 | $0.10 | $0.12 | |
| Microsoft MAI-Transcribe-2 | $0.10 to 31 Dec 2026, meter $0.54 | streaming model listed | |
| AssemblyAI Universal-2 | $0.15 | Universal-Streaming $0.15 | $50 of usage |
| Mistral Voxtral Mini Transcribe 3 | $0.21 | Realtime 3, $0.48 | |
| AssemblyAI Universal-3.5 Pro | $0.21 | Universal-3.6 Pro Realtime $0.45 | $50 of usage |
| ElevenLabs Scribe v2 | $0.22 | Scribe v2 Realtime $0.39 | |
| Mistral Voxtral Small Transcribe 3 | $0.24 | ||
| Speechmatics Melia 1 | $0.24 | $0.40 | $100 of usage |
| Deepgram Nova-3 (English) | $0.26 | $0.46 | $200 of usage |
OpenAI gpt-transcribe | $0.27 | gpt-live-transcribe $1.02 | |
| Google Gemini 3.5 Transcribe | about $0.31 | Live, about $0.54 | Free tier |
| Speechmatics Enhanced | $0.75 | $0.80 | $100 of usage |
Pricing details that change the bill:
- AssemblyAI charges $0.02 an hour extra for speaker labels on files, $0.12 on streams, and $0.05 for keyterm prompting on Universal-3.5 Pro.
- Deepgram drops Nova-3 to $0.0036 a minute on its Growth plan, and charges $0.0052 for multilingual Nova-3.
- ElevenLabs adds $0.05 an hour for keyterm prompting.
- Gladia prices in euros: Solaria-3 at €0.16 an hour async, but Solaria-3 covers five languages.
- Speechmatics takes 33% off if you opt in to model training.
- Gemini's free tier may use your audio to improve Google's products; the paid tier doesn't.
For OpenAI's full line-up, the Whisper shutdown on 26 February 2027 and a 1,000-hour cost comparison, see OpenAI Whisper API pricing.
Latency: the best STT for live audio
For voice agents and live captions, the number that matters is how long after someone stops talking the final text arrives. Artificial Analysis measures this from the detected end of speech on its streaming board:
| Streaming model | AA-WER streaming | Seconds to final text | Per hour |
|---|---|---|---|
| MAI-Transcribe-2-Streaming | 2.5% | 0.13 | $0.54 (AA's listed price) |
| Grok Voice Transcribe 2.0 streaming | 2.8% | 0.25 | $0.20 |
| Gemini 3.5 Transcribe Live | 2.9% | 0.36 | about $0.54 |
| ElevenLabs Scribe v2 Realtime | 3.0% | 0.08 | $0.39 |
| Mistral Voxtral Mini Transcribe Realtime 3 (480 ms) | 3.6% | 0.75 | $0.48 |
| AssemblyAI Universal-3.6 Pro Realtime | 3.6% | 0.14 | $0.45 |
OpenAI gpt-live-transcribe | 4.0% | 0.86 | $1.02 |
| Soniox v5 Real-Time | 4.5% | 0.05 | $0.12 |
| Deepgram Nova-3 Realtime | 6.5% | 0.08 | $0.46 |
| Deepgram Flux | 7.4% | 0.02 | $0.46 |
| AssemblyAI Universal-Streaming English | 8.2% | 0.03 | $0.15 |
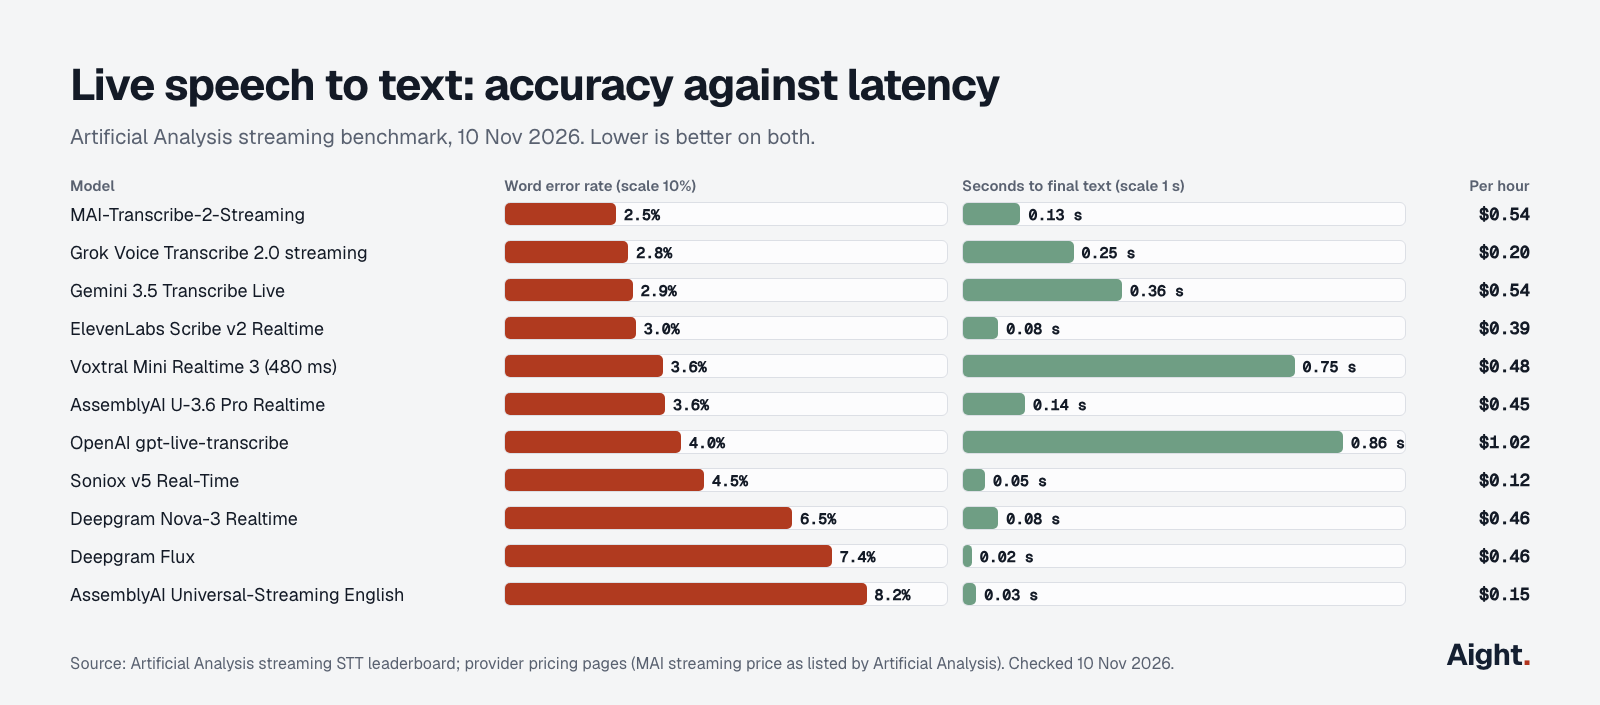
The fastest models give up accuracy: Deepgram Flux returns final text in 0.02 seconds but misses about three times as many words as MAI-Transcribe-2-Streaming. Scribe v2 Realtime is the best balance in this table, 3.0% at 0.08 seconds. For live captions on a tight spend cap, Soniox at $0.12 an hour (4.5%) and Grok at $0.20 (2.8%) cost least.
A few limits from the docs: Gemini 3.5 Transcribe Live sessions last 10 minutes and don't label speakers. Mistral's realtime model can label speakers, but not in the same session as turn detection. Batch speed, for comparison, is rarely the bottleneck: Deepgram Nova-3 runs at 556 times real time and even the slowest leader, gpt-transcribe, at 46.
Diarization: which speech to text APIs label speakers
Diarization means labeling who spoke when. Most leading APIs now include it, but limits and prices differ:
| API | Speaker labels | Limit | Extra cost |
|---|---|---|---|
| ElevenLabs Scribe v2 | Yes | Up to 32 speakers, files up to 10 hours | None listed |
| Microsoft MAI-Transcribe-2 | Yes | Not stated | Included in launch price |
| Mistral Voxtral Transcribe 3 | diarize=true, files and realtime | 10 speakers, up to 8 named reference clips | None listed |
| xAI Grok Voice Transcribe 2.0 | diarize=true | Not stated | None listed |
| Gemini 3.5 Transcribe | Files only | 8 speakers (3+ experimental), 30 minutes per request | None listed |
| AssemblyAI | Files and streams | Not stated | $0.02 an hour on files, $0.12 on streams |
| Deepgram Nova-3 | Files and streams | Not stated | Included on files, $0.12 an hour on streams |
| Soniox | Files and streams | Not stated | Included |
| Speechmatics | Yes, except Melia 1 realtime | Not stated | Included |
| Gladia | Async only | Not stated | Included |
OpenAI gpt-transcribe | No | gpt-4o-transcribe-diarize until 26 Feb 2027 |
Mistral's diarization guide says overlapping speech isn't supported in this version, and speaker numbers only hold within one file. That is common: test crosstalk on your own recordings before you commit. Mistral's Voxtral 3 announcement puts both Voxtral 3 models ahead of MAI-Transcribe-2 and Scribe v2 on cpWER, the speaker-attributed error rate, but that is the vendor's own chart.
Open-weight speech to text models
The best open-weight models now trail the top APIs by less than a percentage point on Artificial Analysis. On the Open ASR Leaderboard (English average WER, 6 November 2026 version):
| Model | Open ASR WER | RTFx | Size | Languages | License |
|---|---|---|---|---|---|
| NVIDIA Nemotron 3.5 Transcribe 30B-A4B | 6.13% | 473 | 30B, 4B active | 40 | OpenMDW-1.1 |
| Qwen3-ASR-1.7B | 6.15% | 836 | 1.7B | 30 plus 22 Chinese dialects | Apache 2.0 |
| IBM Granite Speech 5.0 2B | 6.68% | 548 | 2B | English plus 5 | Apache 2.0 |
| Cohere Transcribe 03-2026 | 6.72% | 924 | 2B | 14 | Apache 2.0 |
| NVIDIA Canary-Qwen-2.5B | 6.92% | 882 | 2.5B | English | CC-BY-4.0 |
| NVIDIA Parakeet TDT 0.6B v2 | 6.93% | 6,148 | 0.6B | English | CC-BY-4.0 |
| NVIDIA Parakeet TDT 0.6B v3 | 7.04% | 6,322 | 0.6B | 25 European | CC-BY-4.0 |
| Mistral Voxtral Small 24B (2507) | 7.44% | 101 | 24B | 8 | Apache 2.0 |
| OpenAI Whisper large-v3 | 8.24% | 471 | 1.55B | 99 | Apache 2.0 on Hugging Face |
| OpenAI Whisper large-v3-turbo | 8.75% | 809 | 0.8B | 99 | MIT |
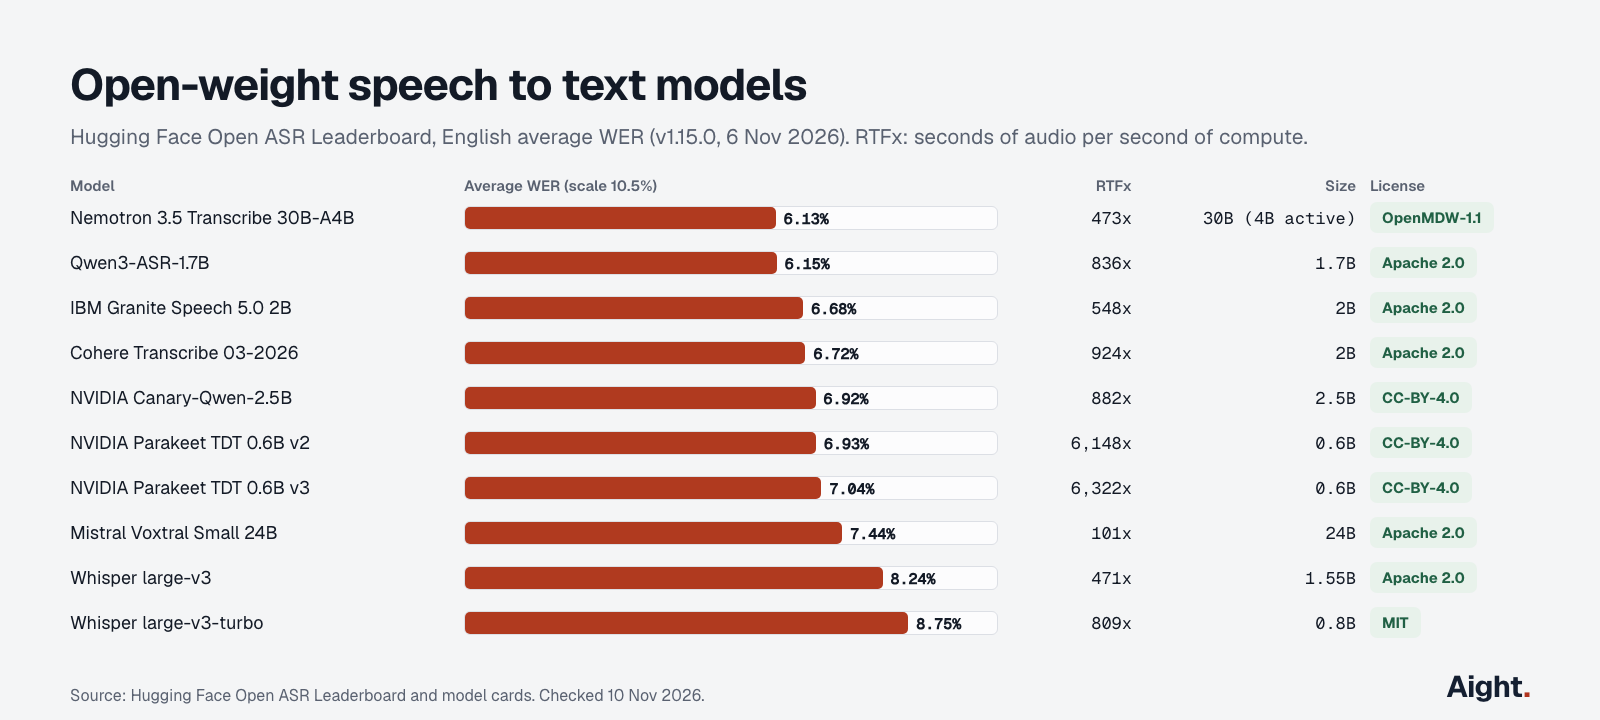
How to choose among them:
- Nemotron 3.5 Transcribe, released 28 October 2026, is the most accurate open model on both leaderboards (2.8% on Artificial Analysis, 4.69% on the multilingual Open ASR board, ahead of Soniox's API). It handles up to an hour per file, can tag speakers and word timestamps, and NVIDIA's quick start targets one 80 GB H100. It is offline only, not a streaming model.
- Qwen3-ASR-1.7B is almost as accurate at a fraction of the size and is the pick for Chinese dialects. Word timestamps need the separate Qwen3-ForcedAligner, which handles up to five minutes.
- Parakeet TDT 0.6B v2 and v3 process audio more than 6,000 times faster than real time on the leaderboard's GPU, which makes them the choice for large backlogs and laptops. CC-BY-4.0 requires attribution.
- Whisper large-v3 still has the widest language list but now ranks 42nd of 63 on the English board.
For live audio, open options are thinner. Voxtral Mini 4B Realtime (February 2026, Apache 2.0) scores 4.5% on the Artificial Analysis streaming board at 0.67 seconds. NVIDIA's Nemotron streaming models trade accuracy for delay: 5.4% at a 1,120 ms chunk, 8.4% at 80 ms. Mistral hasn't released Voxtral 3 weights; its announcement offers self-deployment through its sales team.
Self-hosting only beats an API on cost at volume. At $0.10 an hour for Grok or Soniox, 10,000 hours of audio a month costs $1,000, which has to cover a GPU, its operation and your engineering time. The usual reasons to self-host are data that can't leave your network, offline devices, or fine-tuning for a domain. If data handling is the concern, the zero data retention guide covers what each API provider keeps.
Pick the best speech to text API by job
| Job | First pick | Why | Alternative |
|---|---|---|---|
| Highest accuracy, recorded English | MAI-Transcribe-2 | 2.0%, $0.10 an hour to 31 Dec 2026 | Voxtral Small Transcribe 3, 2.1%, $0.24 |
| Lowest cost at high accuracy | Grok Voice Transcribe 2.0 | 2.3% at $0.10 an hour, word timestamps | Soniox v5, $0.10 with speaker labels included |
| Meetings and interviews | ElevenLabs Scribe v2 | Up to 32 speakers, 10-hour files | Voxtral Small Transcribe 3, named speakers |
| Many languages | ElevenLabs Scribe v2 | 90+ languages, 3.57% on the multilingual board | Gemini 3.5 Transcribe, 85+ languages |
| Voice agents | ElevenLabs Scribe v2 Realtime | 3.0% at 0.08 s | MAI-Transcribe-2-Streaming, 2.5% at 0.13 s |
| Live captions on a low spend cap | Grok streaming | 2.8% at $0.20 an hour | Soniox v5, 4.5% at $0.12 |
| Google Cloud shops | Gemini 3.5 Transcribe | 2.6%, free tier for tests | Gemini 3.5 Transcribe Live for streams, 2.9% |
| Already on OpenAI | gpt-transcribe | 3.3%, $0.27 an hour | Move before Whisper shuts down on 26 Feb 2027 |
| Self-hosted, best accuracy | Nemotron 3.5 Transcribe | 2.8%, OpenMDW license | Qwen3-ASR-1.7B, Apache 2.0 |
| Self-hosted, fastest | Parakeet TDT 0.6B v3 | 6,322x real time, 25 languages | Whisper large-v3-turbo for other languages |
Whatever the table says, run 30 to 60 minutes of your own audio through two or three candidates before you sign anything. Accents, phone-line audio, crosstalk, product names and numbers move error rates more than the gaps between the top ten models. Most providers here start you with free usage: Deepgram $200, Speechmatics $100, AssemblyAI $50, and Gemini's free tier.
After the transcript: summaries through Aight
Aight doesn't offer a transcription endpoint. Its documented routes are chat completions, embeddings and the model list, so transcribe with one of the APIs above and send the text on.
Where Aight fits is the next step most transcription pipelines take: summarizing calls, pulling action items or answering questions over the text. Aight gives you one OpenAI-compatible key at https://api.getaight.ai/v1 for 138 models from 16 makers, at the maker's list price on most models, with a monthly spend cap and allowed-model list per key. Google estimates 175 text tokens per minute of speech, about 10,500 tokens for a one-hour call, so summarizing it with a small model costs a fraction of a cent; the token calculator gives the exact figure for the model you pick. If you embed transcripts for search, the best embedding models post compares the options, and best LLM API covers the text models. Prompts and outputs aren't stored or used for training.
What developers report
- "The real gaps are in latency, handling interruptions" (Hacker News commenter who builds voice agents, 21 Oct 2026, link), arguing that WER is good enough across many providers.
- MAI-Transcribe-2 "generally seems like the best model right now" (Hacker News commenter, 17 Sep 2026, link).
- "Nothing for Voxtral 3 is on Hugging Face." The commenter points to Voxtral Mini 4B Realtime (Apache 2.0) as Mistral's latest open model (Hacker News, 21 Oct 2026, link).
- A commenter notes Nemotron 3.5 Transcribe is built for recorded audio only and uses NVIDIA's Nemotron Streaming model for German and English dictation instead (Hacker News, 28 Oct 2026, link).
- A commenter reports Parakeet transcribes stutters literally, word fragment by fragment, where Whisper smooths them out (Hacker News, 13 Jul 2026, link).
FAQ
What is the most accurate speech to text API?
On Artificial Analysis on 10 November 2026, Microsoft's MAI-Transcribe-2 leads production models at 2.0% word error rate, with Mistral Voxtral Small Transcribe 3 (2.1%) and ElevenLabs Scribe v2 (2.2%) close behind. Alibaba's Fun-Realtime-ASR scores 1.7% but is a preview. On the Hugging Face Open ASR board, Zoom Scribe v2.1 Pro ranks first in English and Microsoft first in multilingual.
What is the cheapest speech to text API?
xAI Grok Voice Transcribe 2.0, Soniox v5 and MAI-Transcribe-2 all charge $0.10 an hour for recorded audio, though Microsoft's price is a launch offer that ends with 2026. Of the three, Grok has the lowest error rate (2.3%). For live audio, Soniox is lowest at $0.12 an hour.
Is Whisper still the best speech to text model?
No. Whisper large-v3 ranks 42nd of 63 on the Open ASR Leaderboard's English board, and OpenAI's own whisper-1 scores 4.1% on Artificial Analysis against 2.0% for the leader. OpenAI shuts whisper-1 down on 26 February 2027 and recommends gpt-transcribe.
What is the best open-source speech to text model?
NVIDIA's Nemotron 3.5 Transcribe is the most accurate open-weight model on both public leaderboards, under the OpenMDW license. For smaller hardware, Qwen3-ASR-1.7B (Apache 2.0) is nearly as accurate, and Parakeet TDT 0.6B v3 (CC-BY-4.0) is the fastest.
Which speech to text API has the lowest latency?
On the Artificial Analysis streaming board, Deepgram Flux returns final text 0.02 seconds after speech ends, and AssemblyAI Universal-Streaming 0.03 seconds, but both miss 7% to 8% of words. ElevenLabs Scribe v2 Realtime (0.08 s, 3.0%) and MAI-Transcribe-2-Streaming (0.13 s, 2.5%) pair low delay with high accuracy.
Sources
- Artificial Analysis: Speech to text leaderboard, Streaming leaderboard
- Hugging Face: Open ASR Leaderboard (version 1.15.0), model cards for Nemotron 3.5 Transcribe, Qwen3-ASR-1.7B, Cohere Transcribe, Granite Speech 5.0 2B, Parakeet TDT 0.6B v3, Parakeet TDT 0.6B v2, Canary-Qwen-2.5B, Voxtral Small 24B, Voxtral Mini 4B Realtime, Whisper large-v3, Whisper large-v3-turbo
- Microsoft: MAI-Transcribe-2 announcement, MAI-Transcribe-2 model page, Azure Retail Prices API
- Mistral: Pricing, Diarize speakers, Voxtral 3 announcement
- ElevenLabs: API pricing, Speech to text docs
- xAI: Pricing, Speech to text docs
- Google: Gemini API pricing, Gemini 3.5 Transcribe
- AssemblyAI, Pricing; Deepgram, Pricing; Soniox, Pricing; Speechmatics, Pricing; Gladia, Pricing
- OpenAI, API pricing
- Hacker News: comments 50175042, 49747122, 50178093, 50277985, 48895644
- Aight: Models and pricing, API reference, Token calculator
Checked on 10 November 2026. Updated 17 November 2026: Aight's current model list.